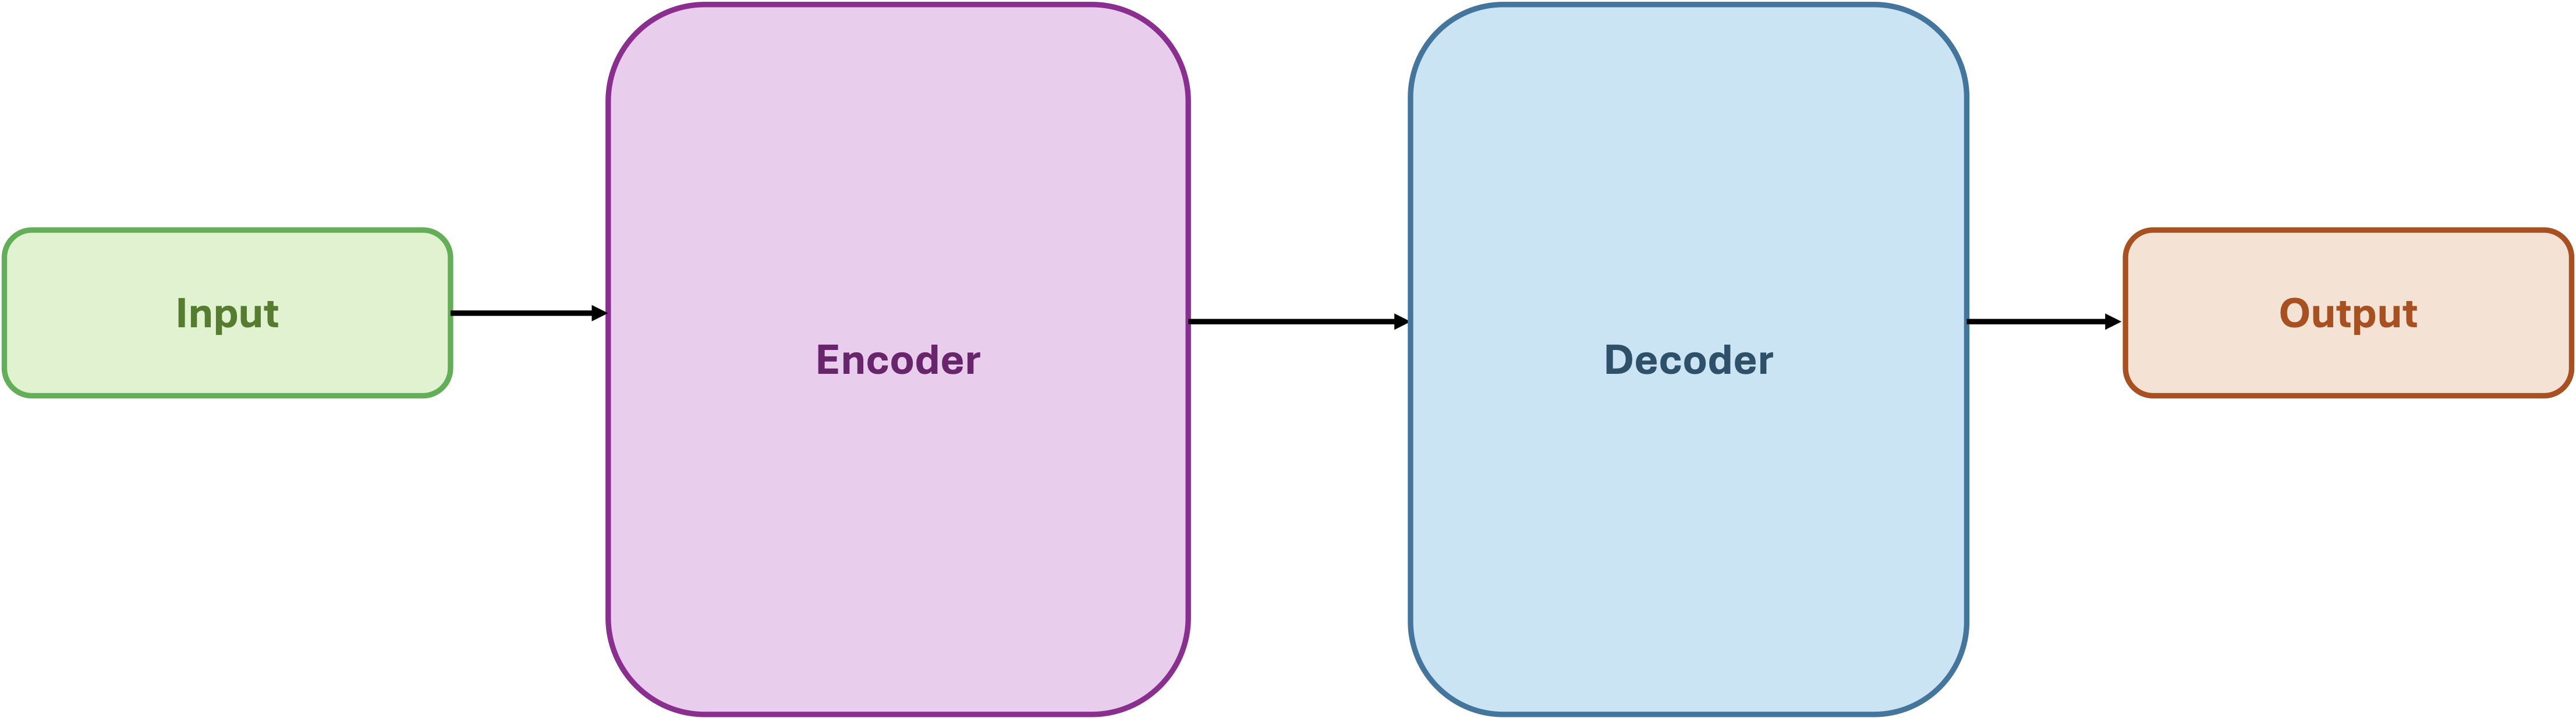
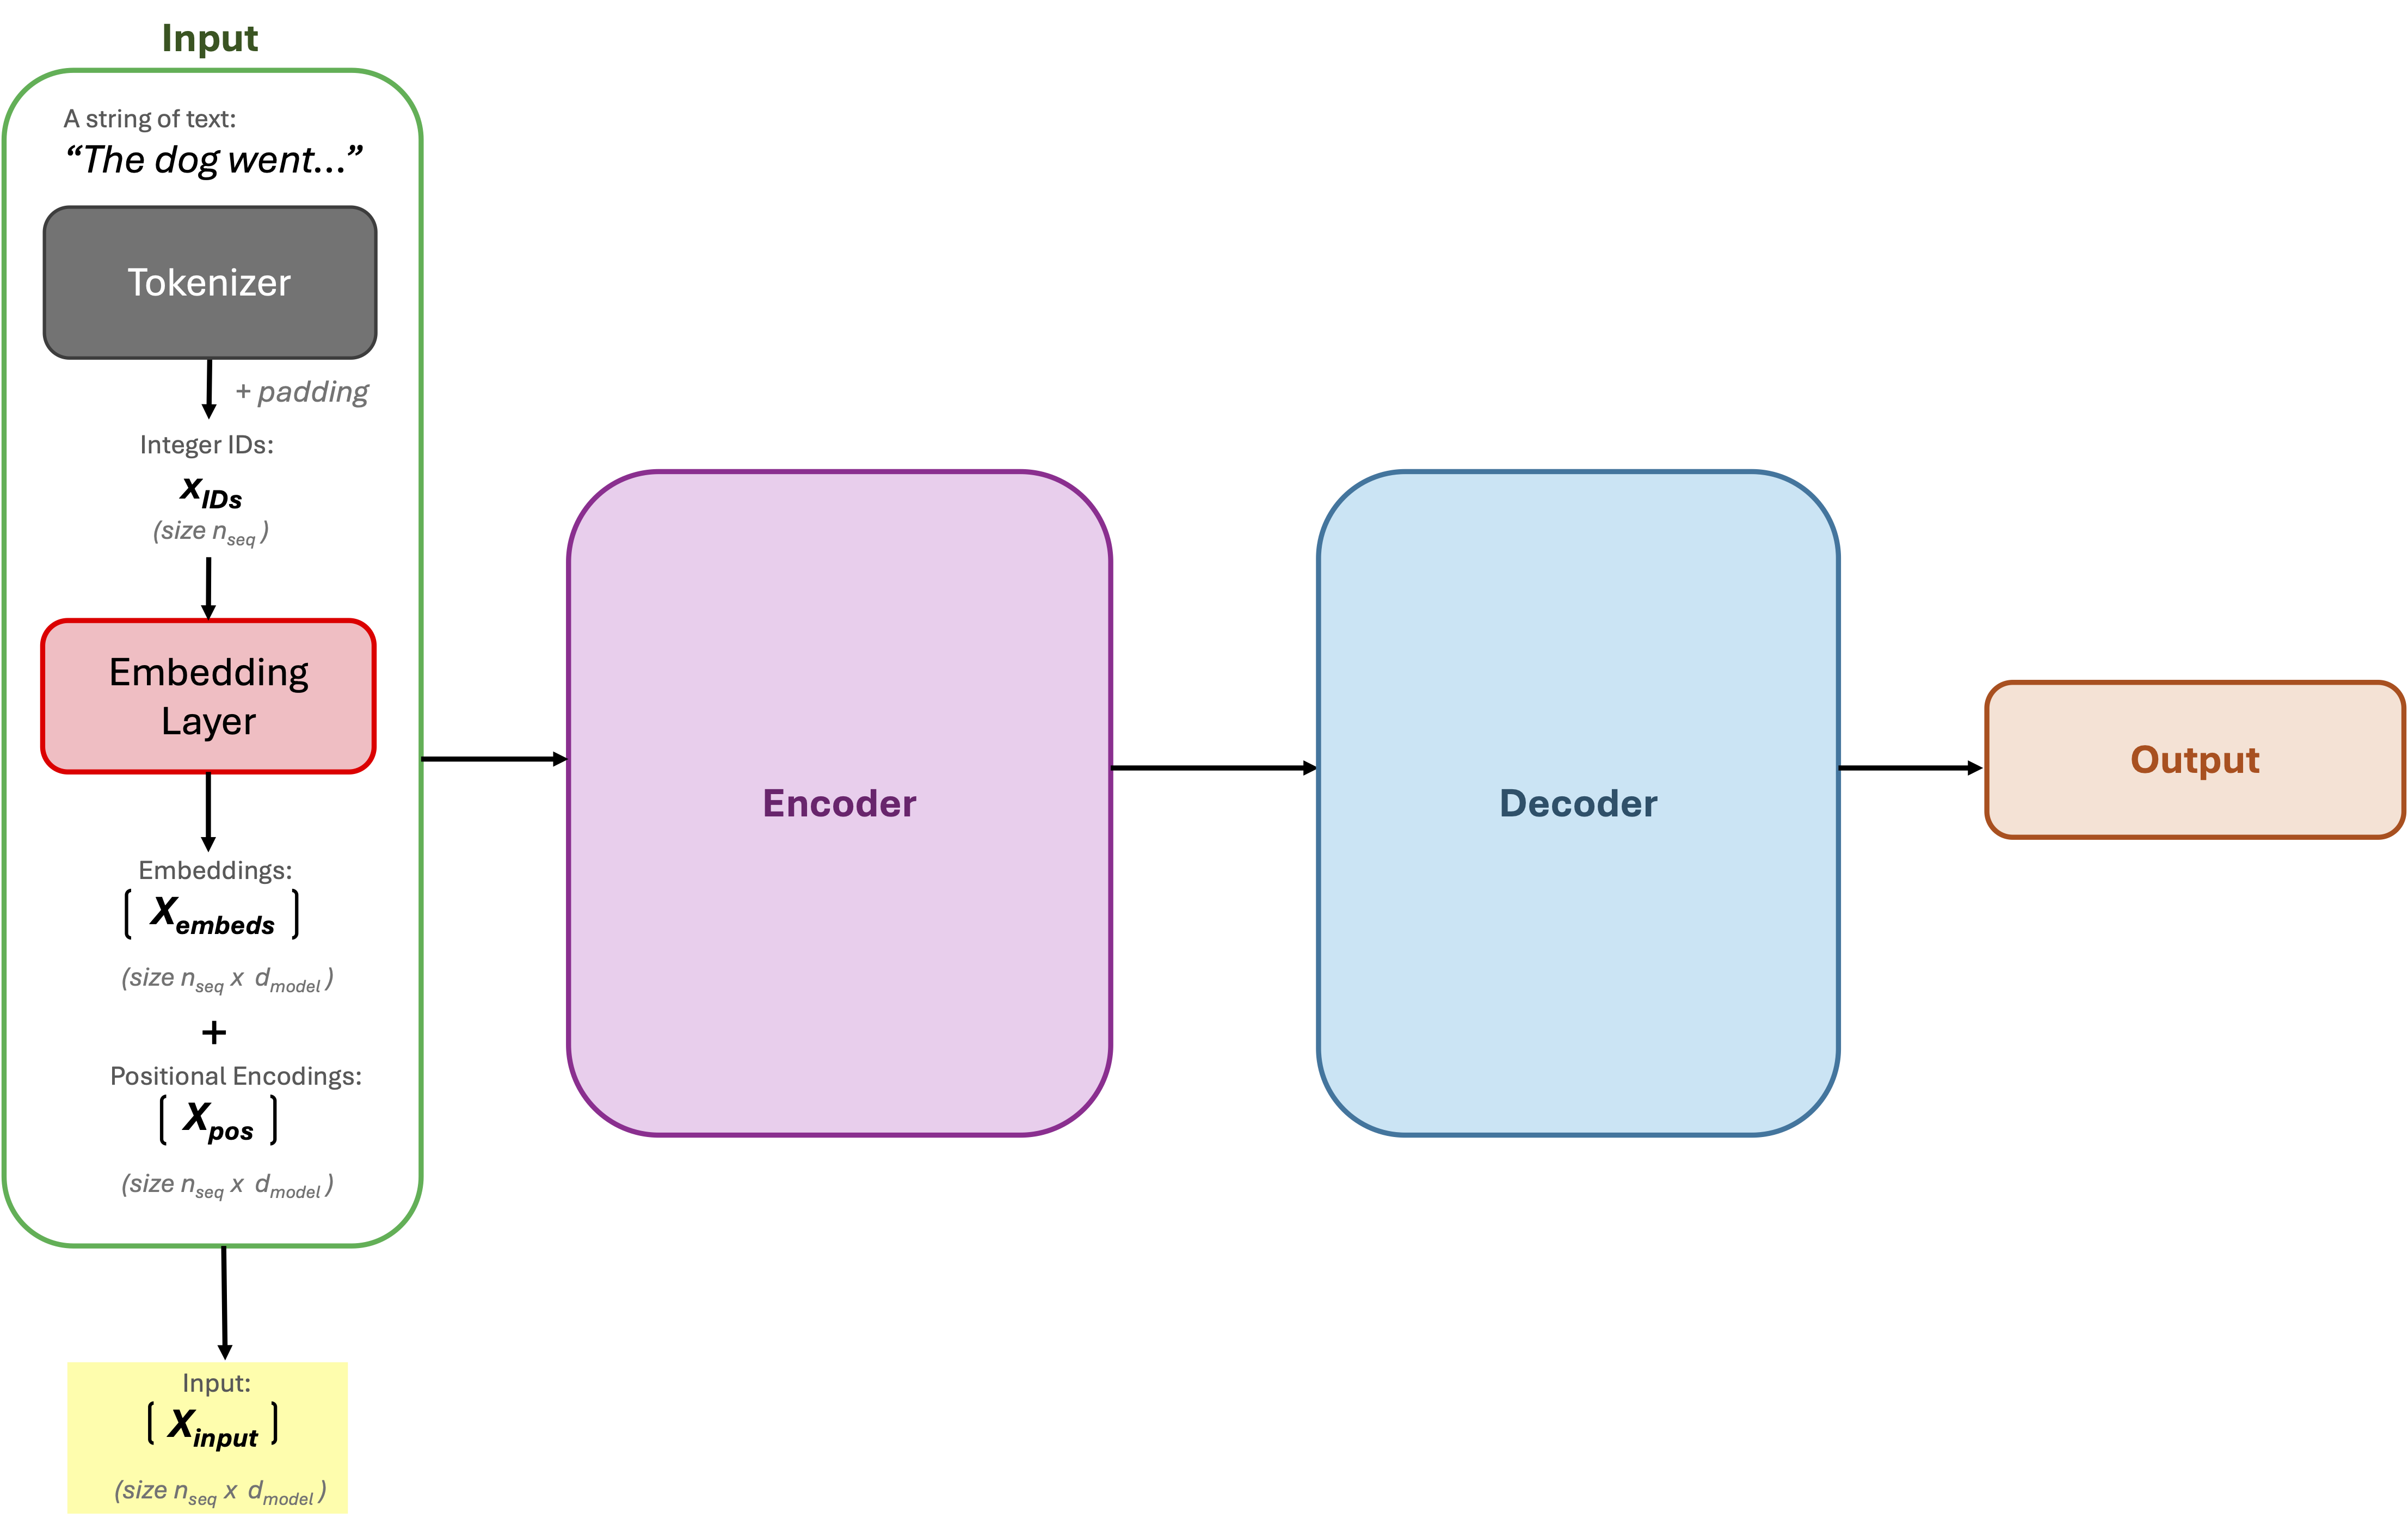
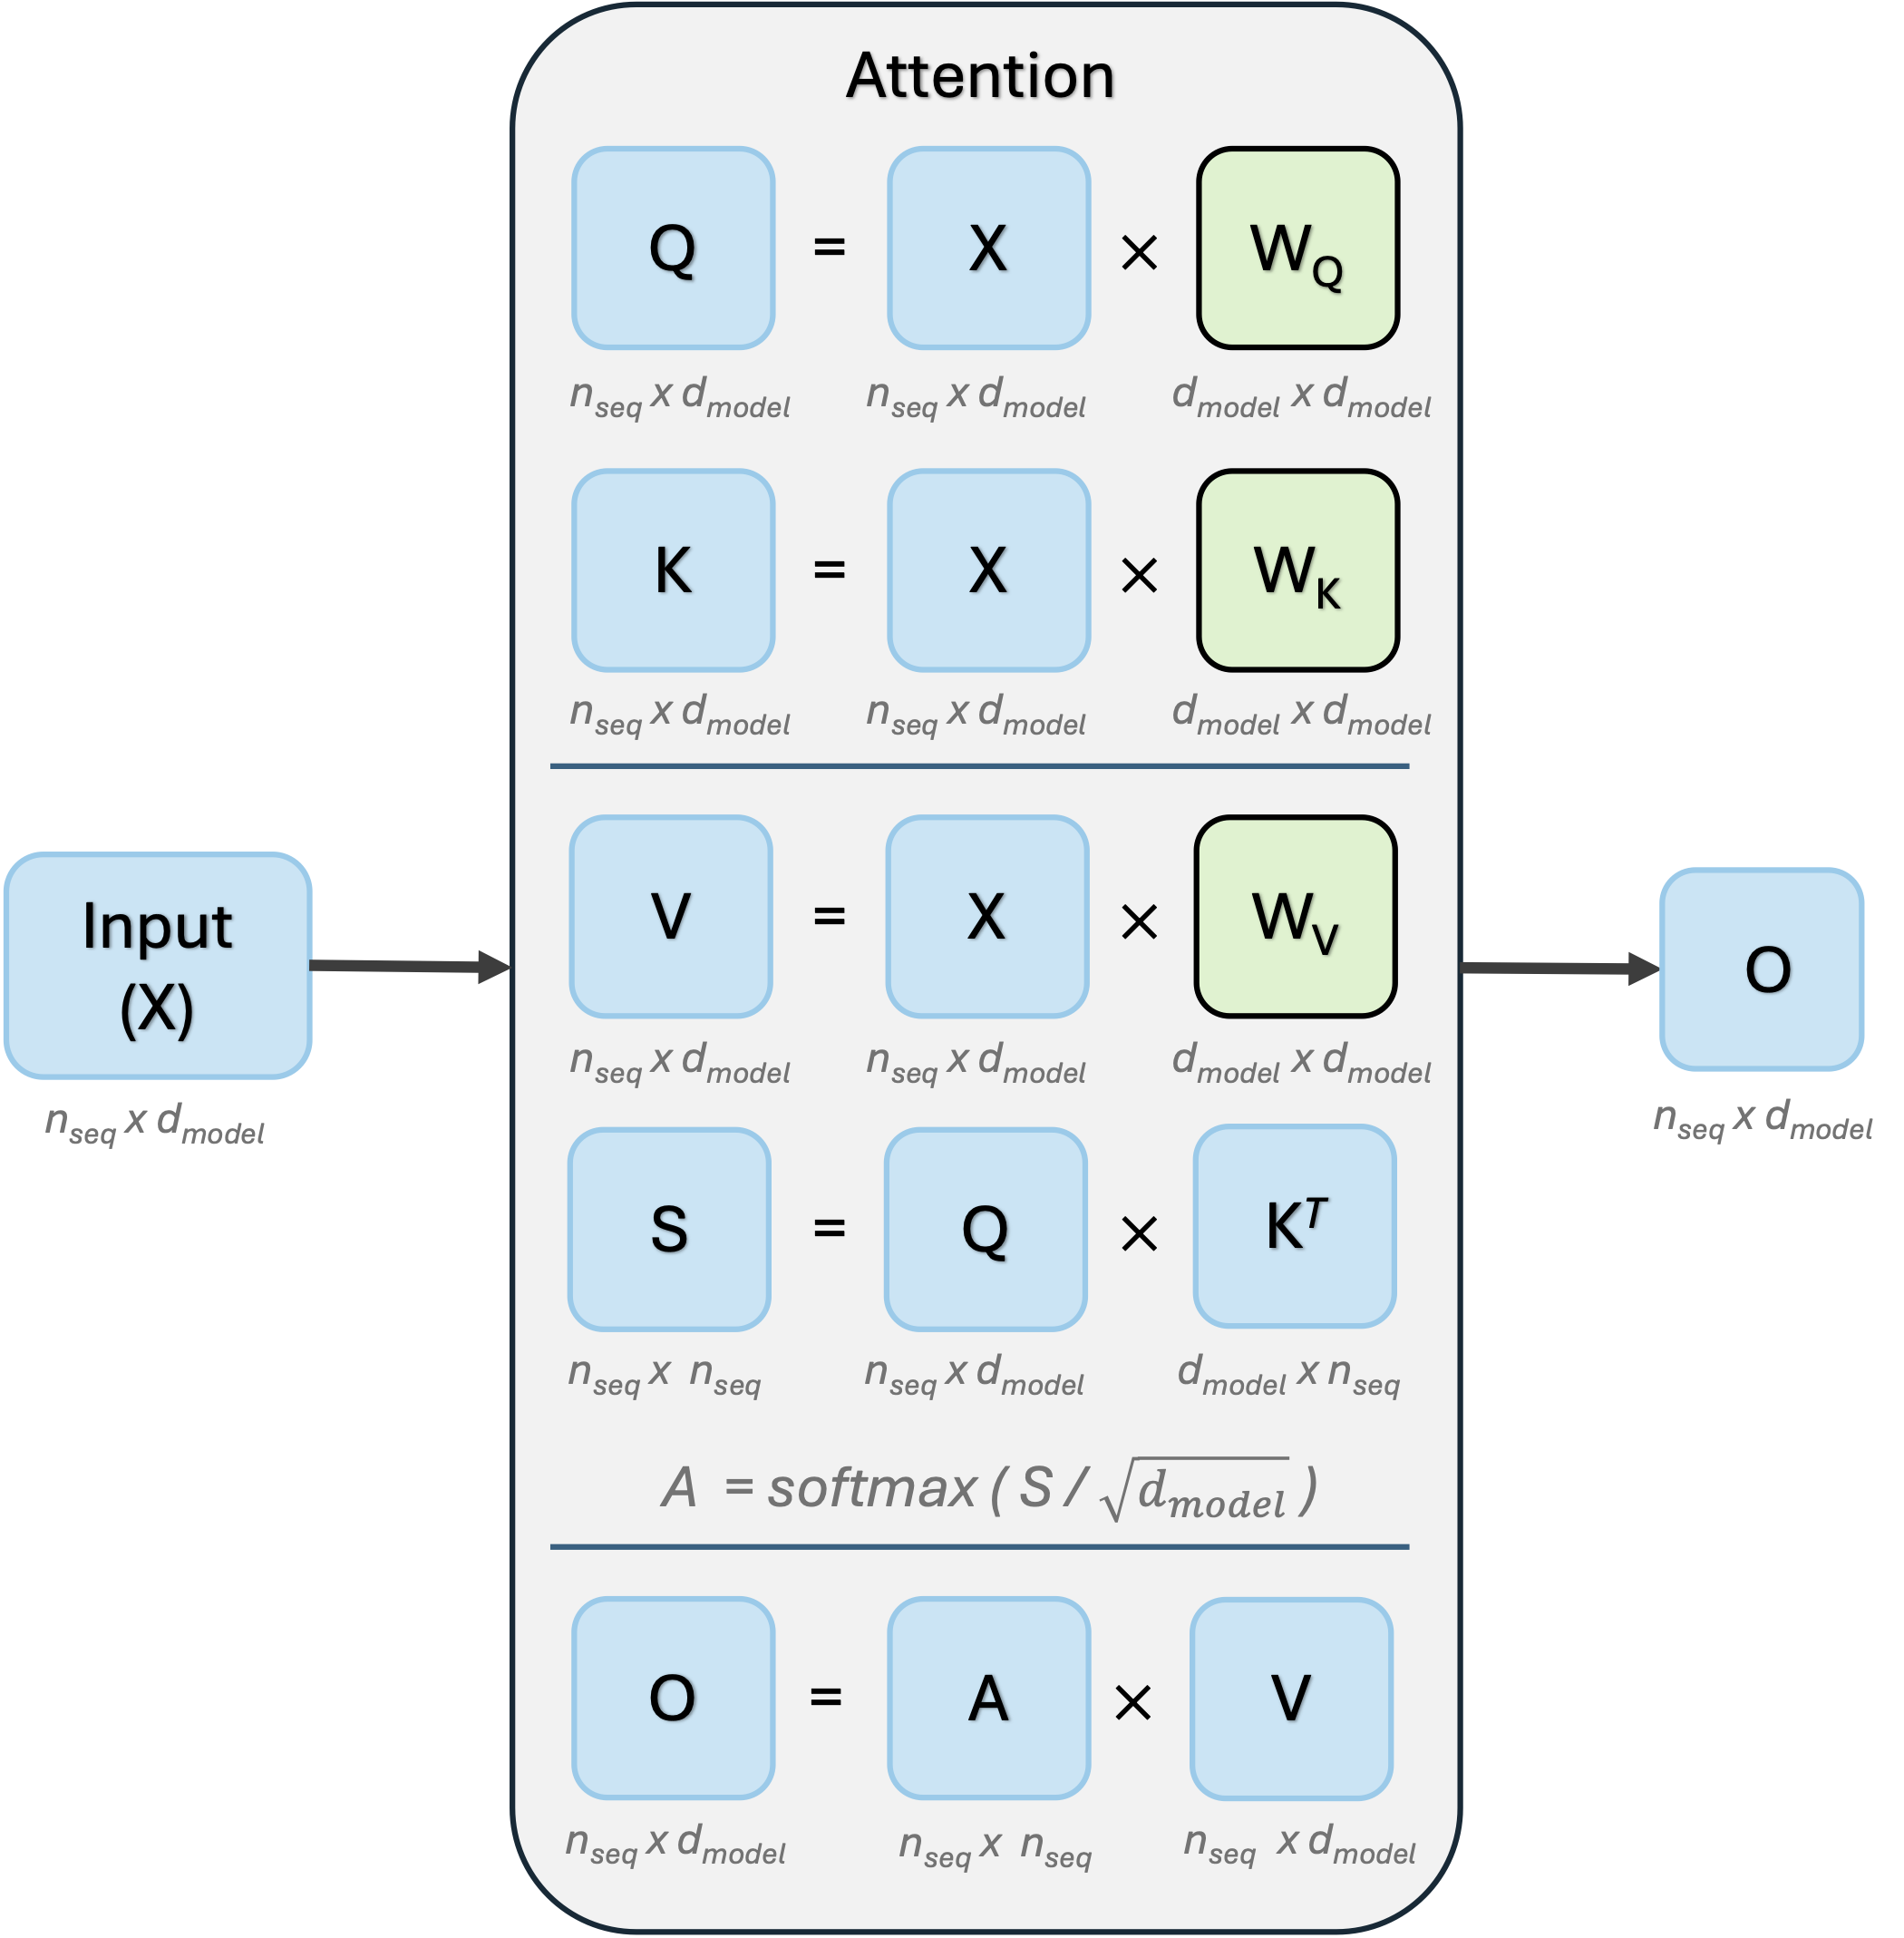
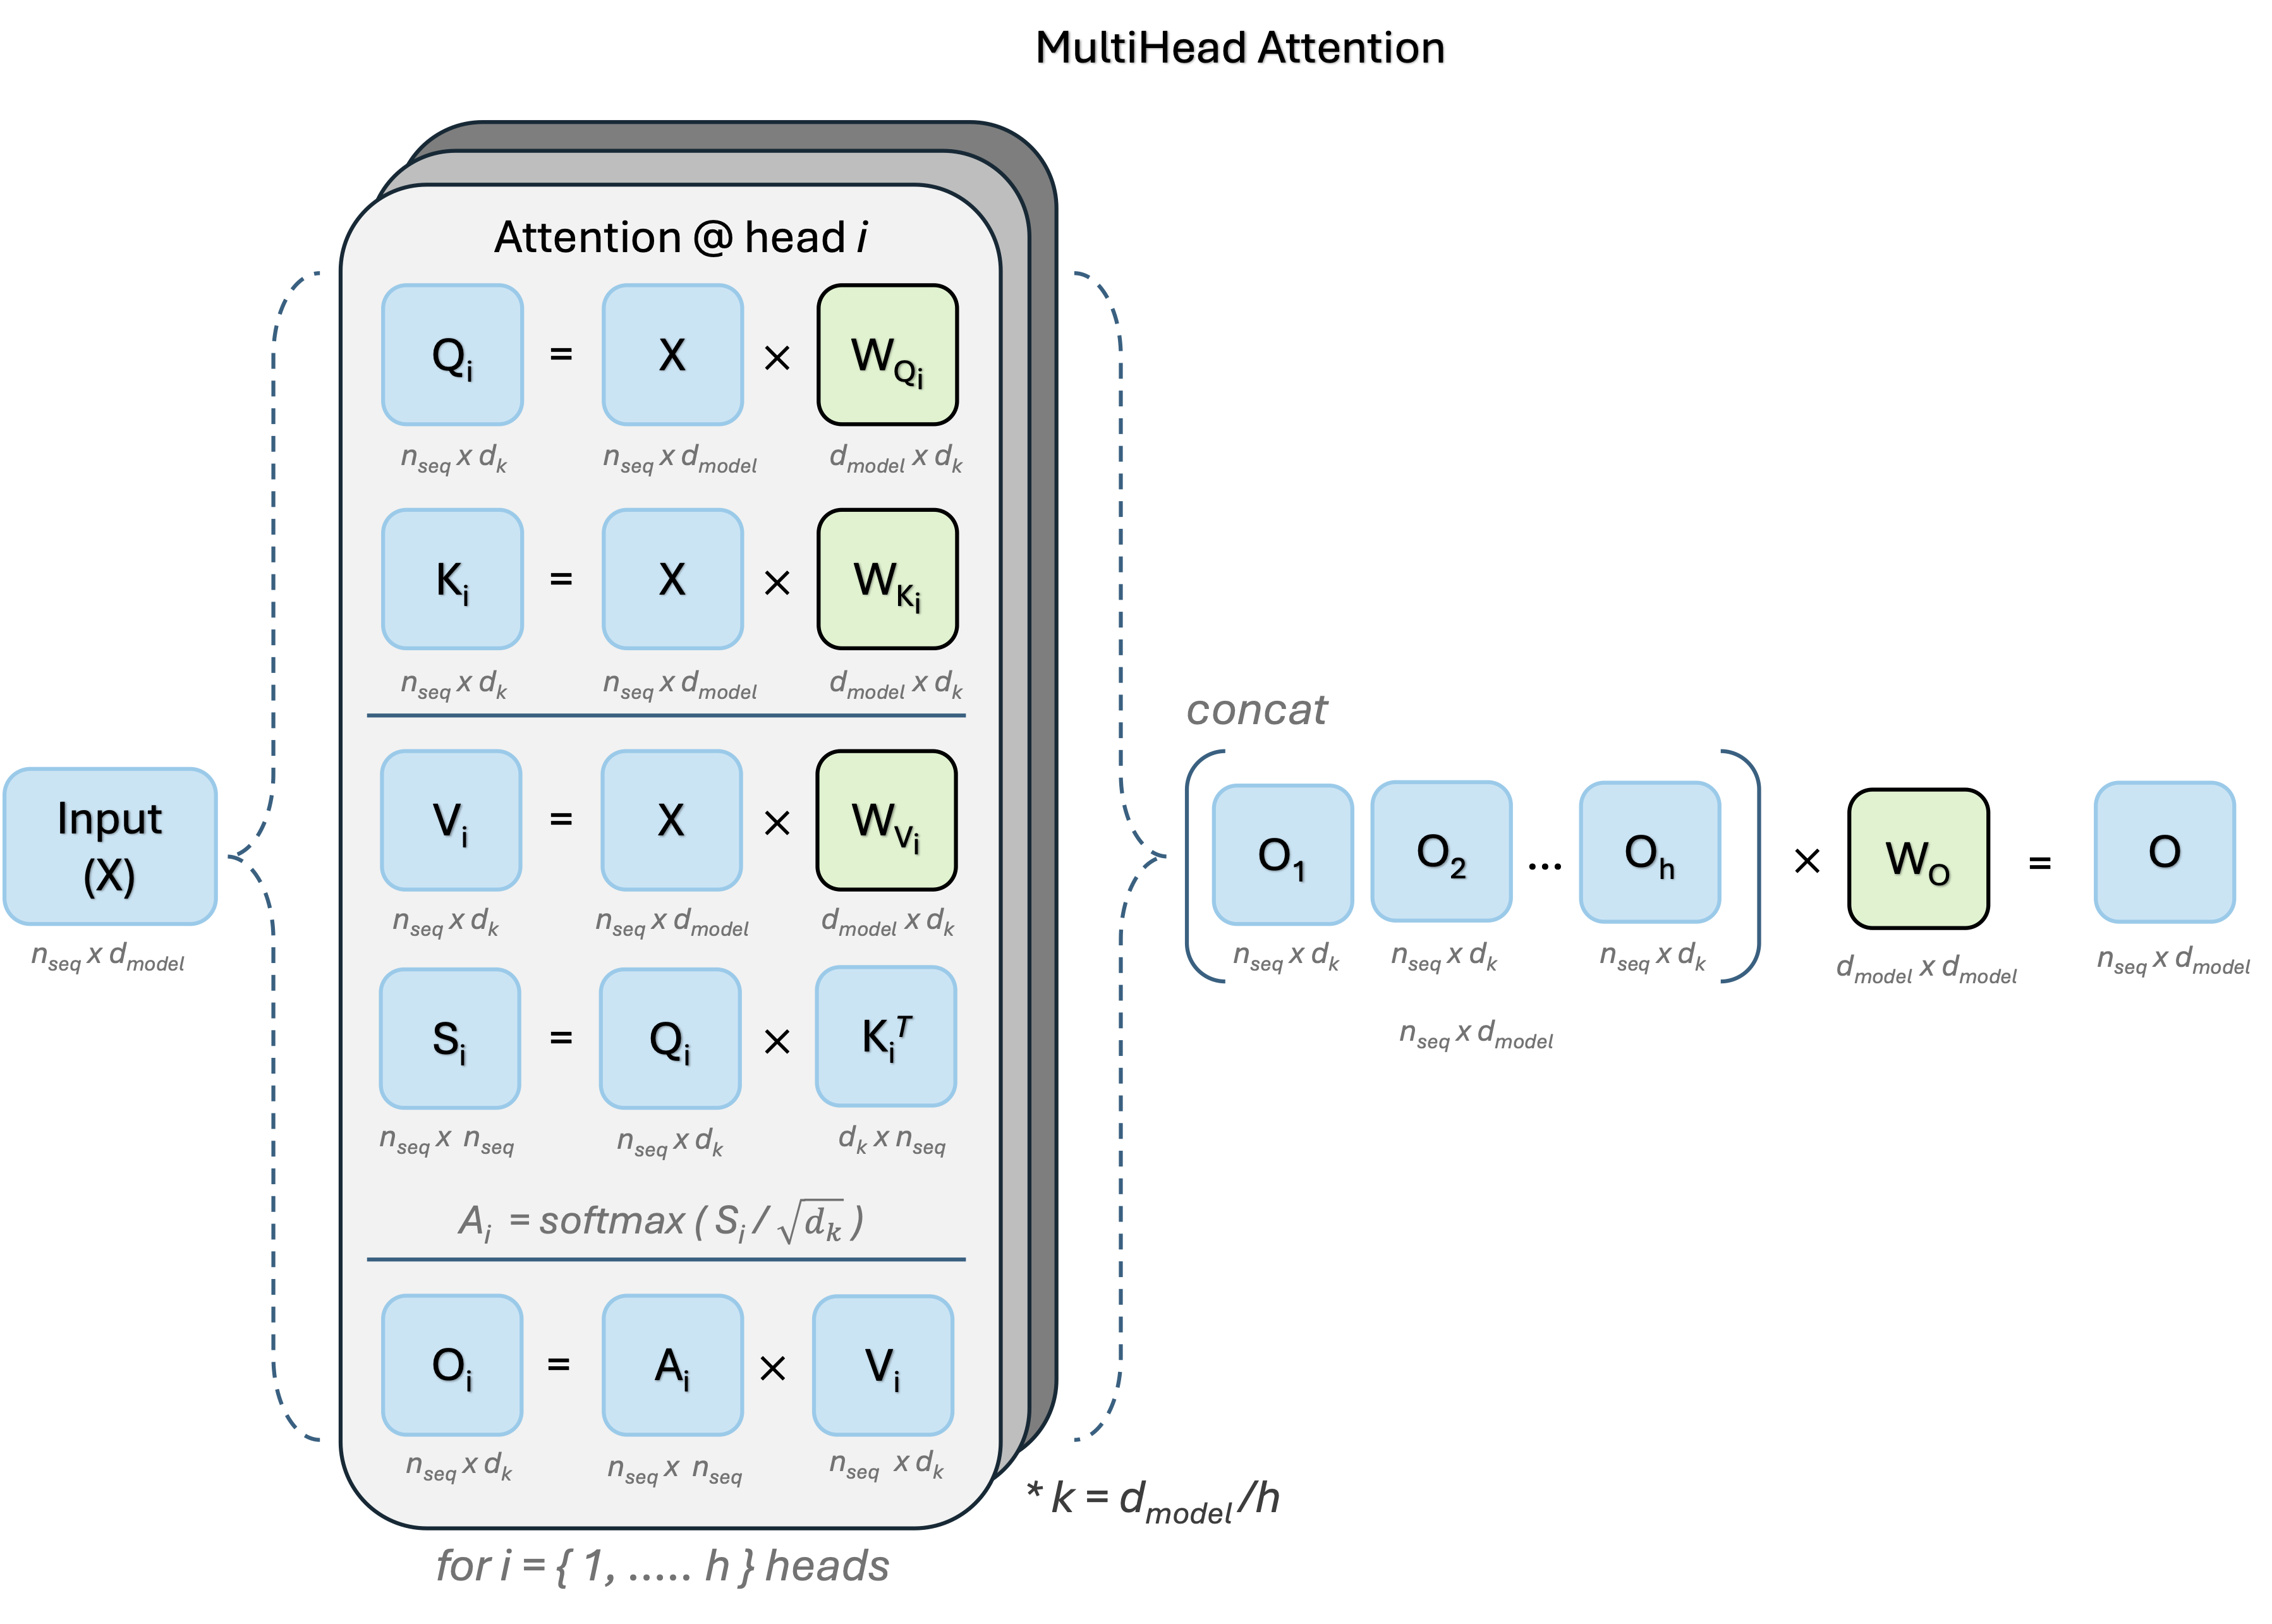
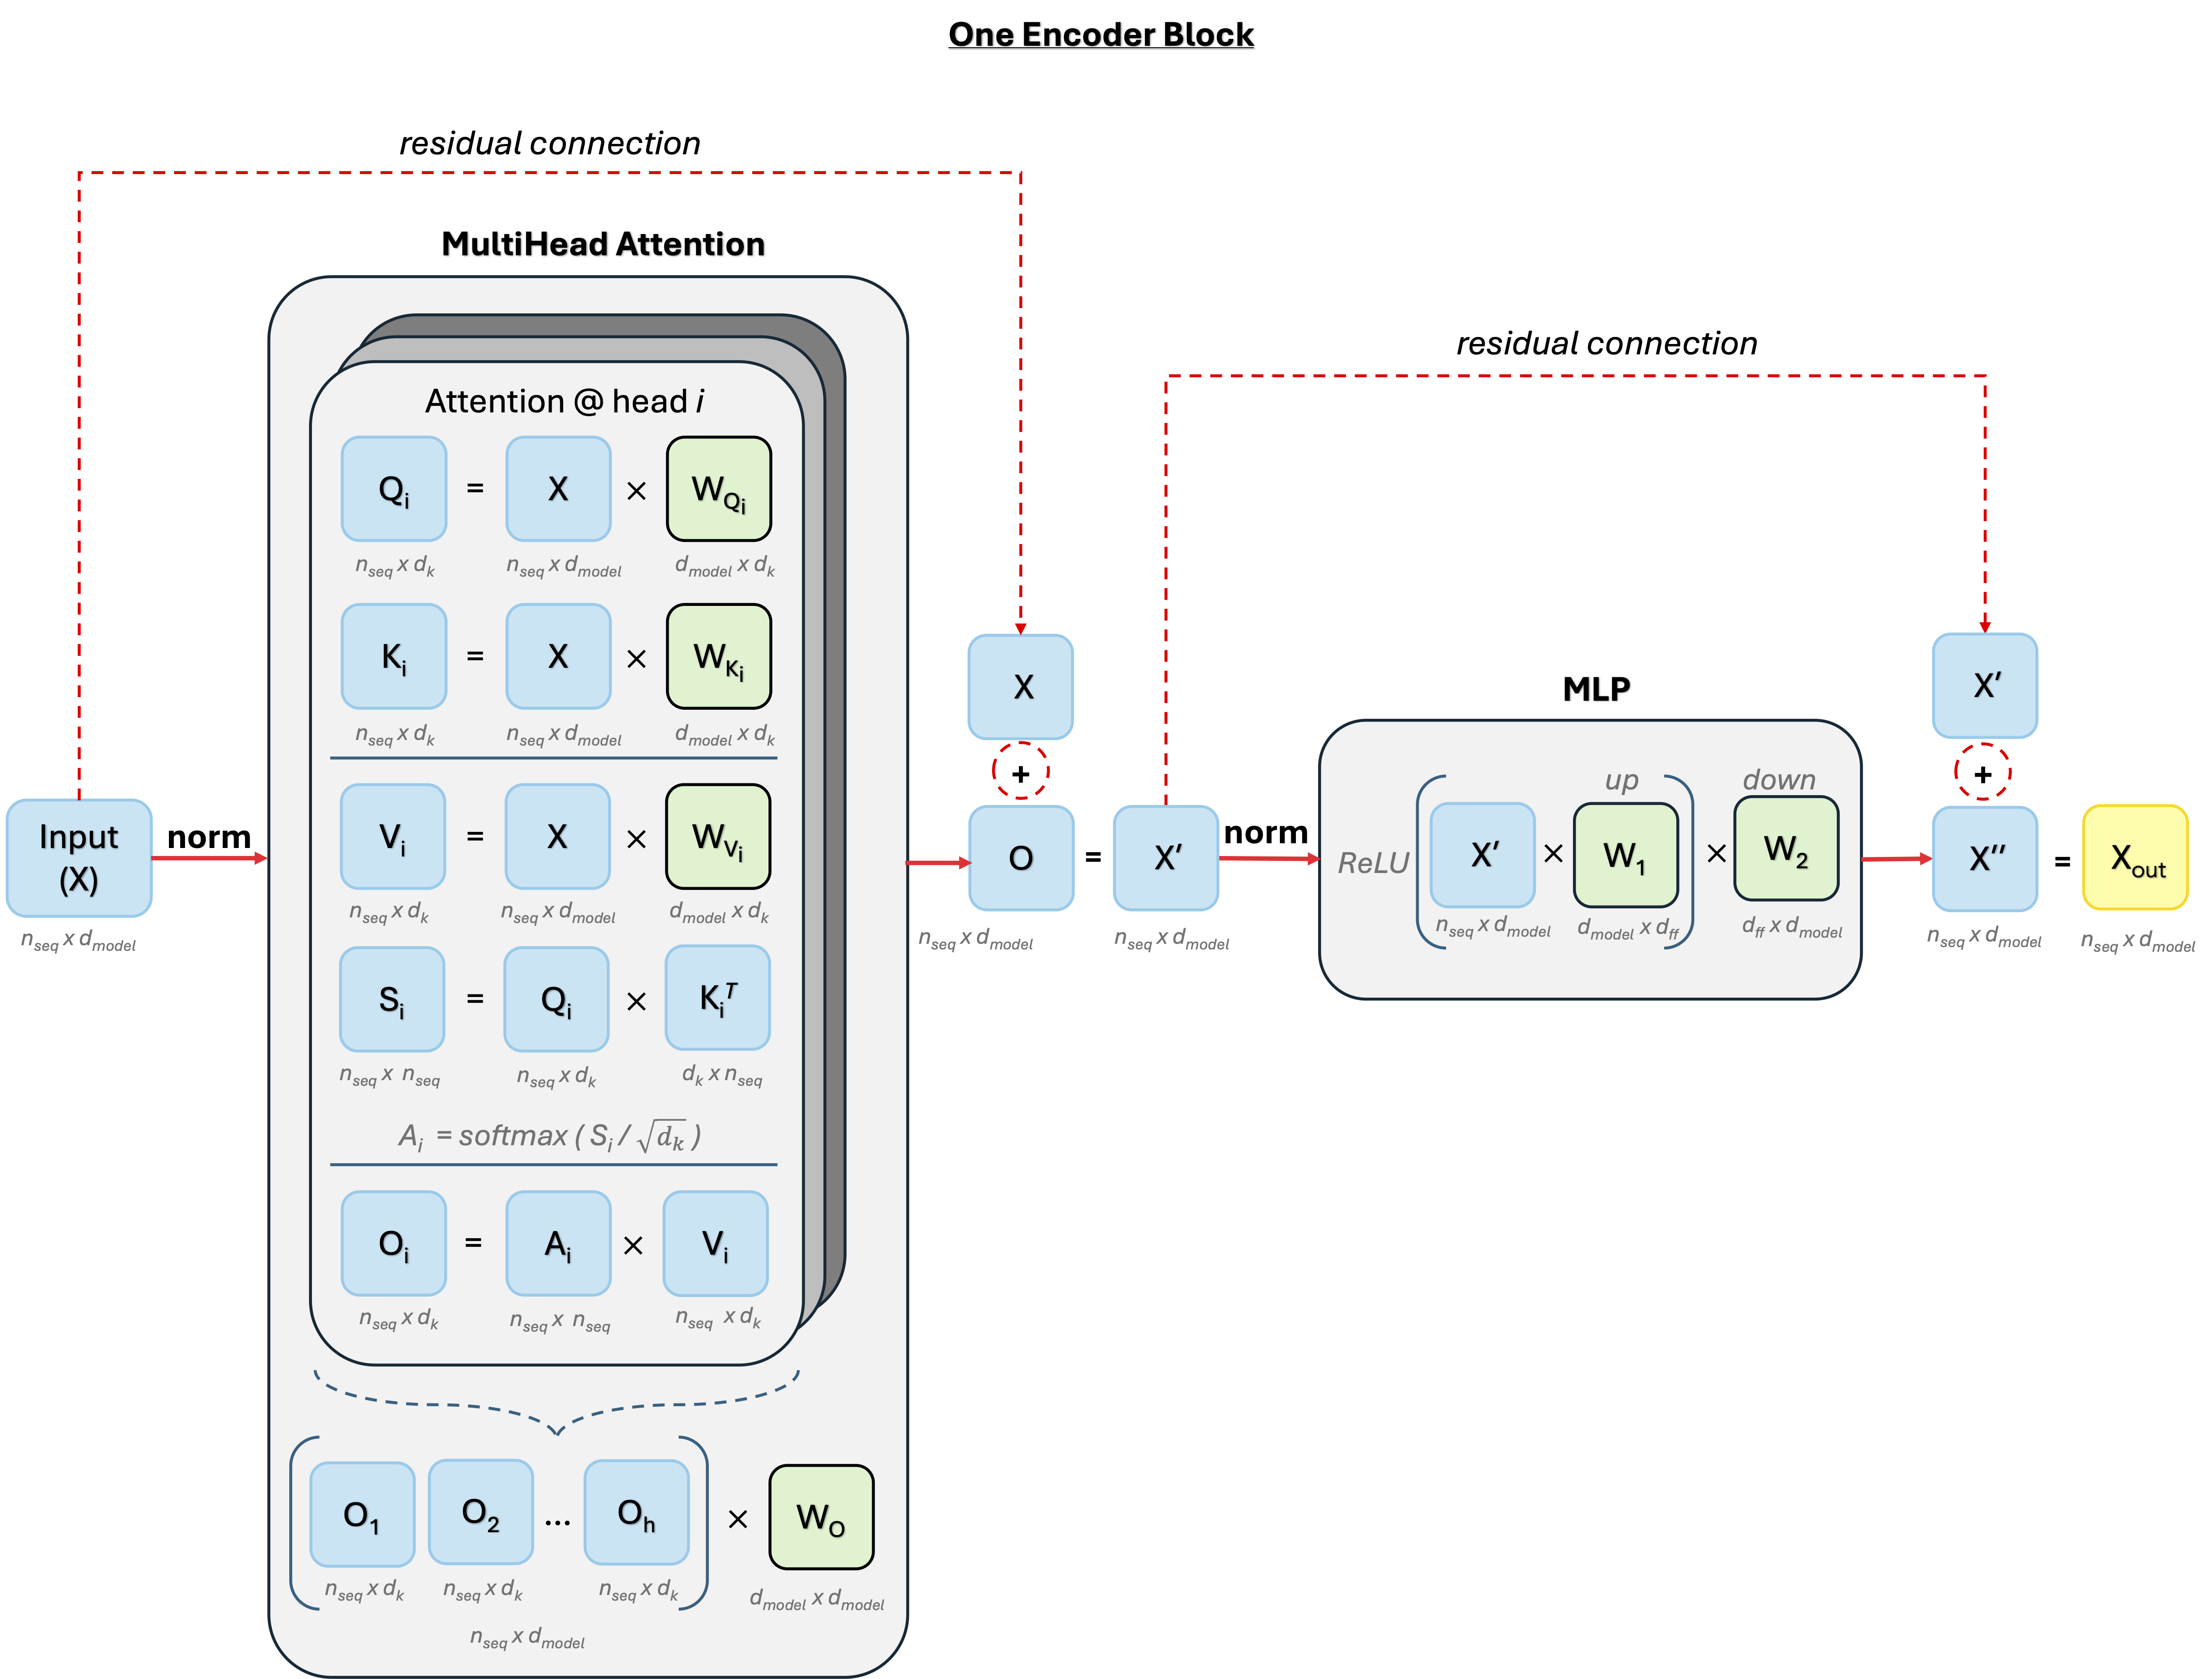
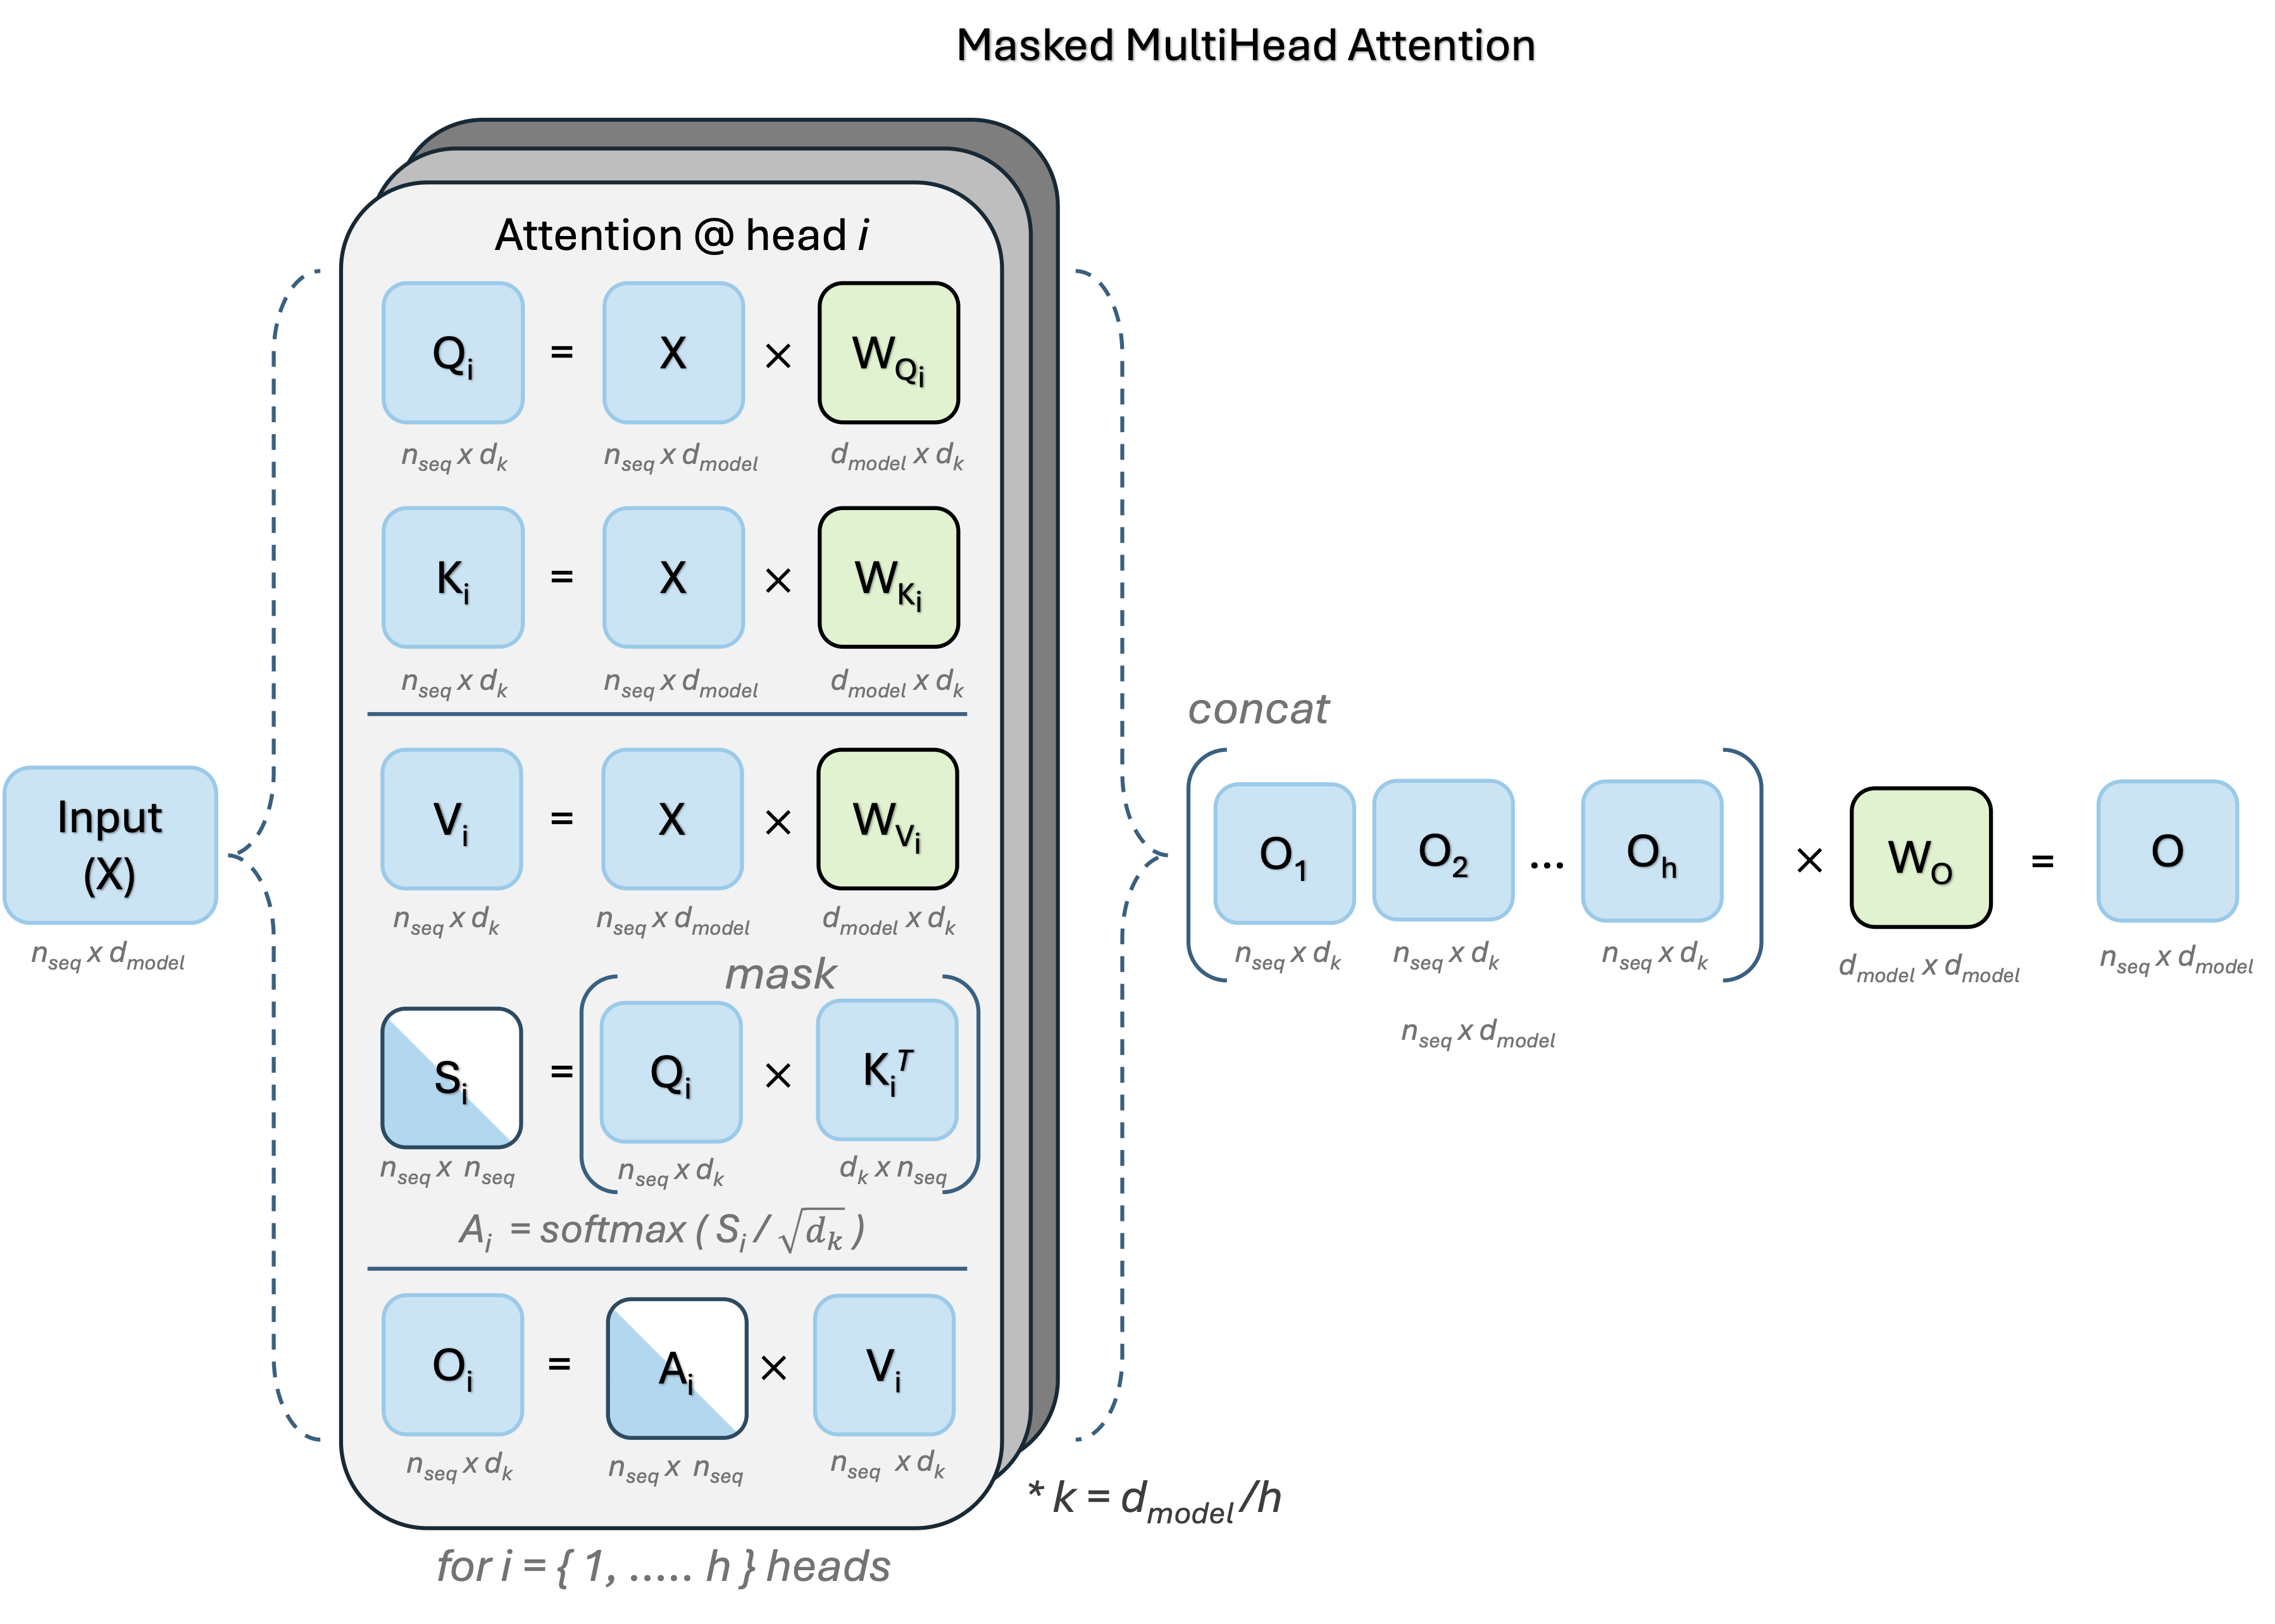
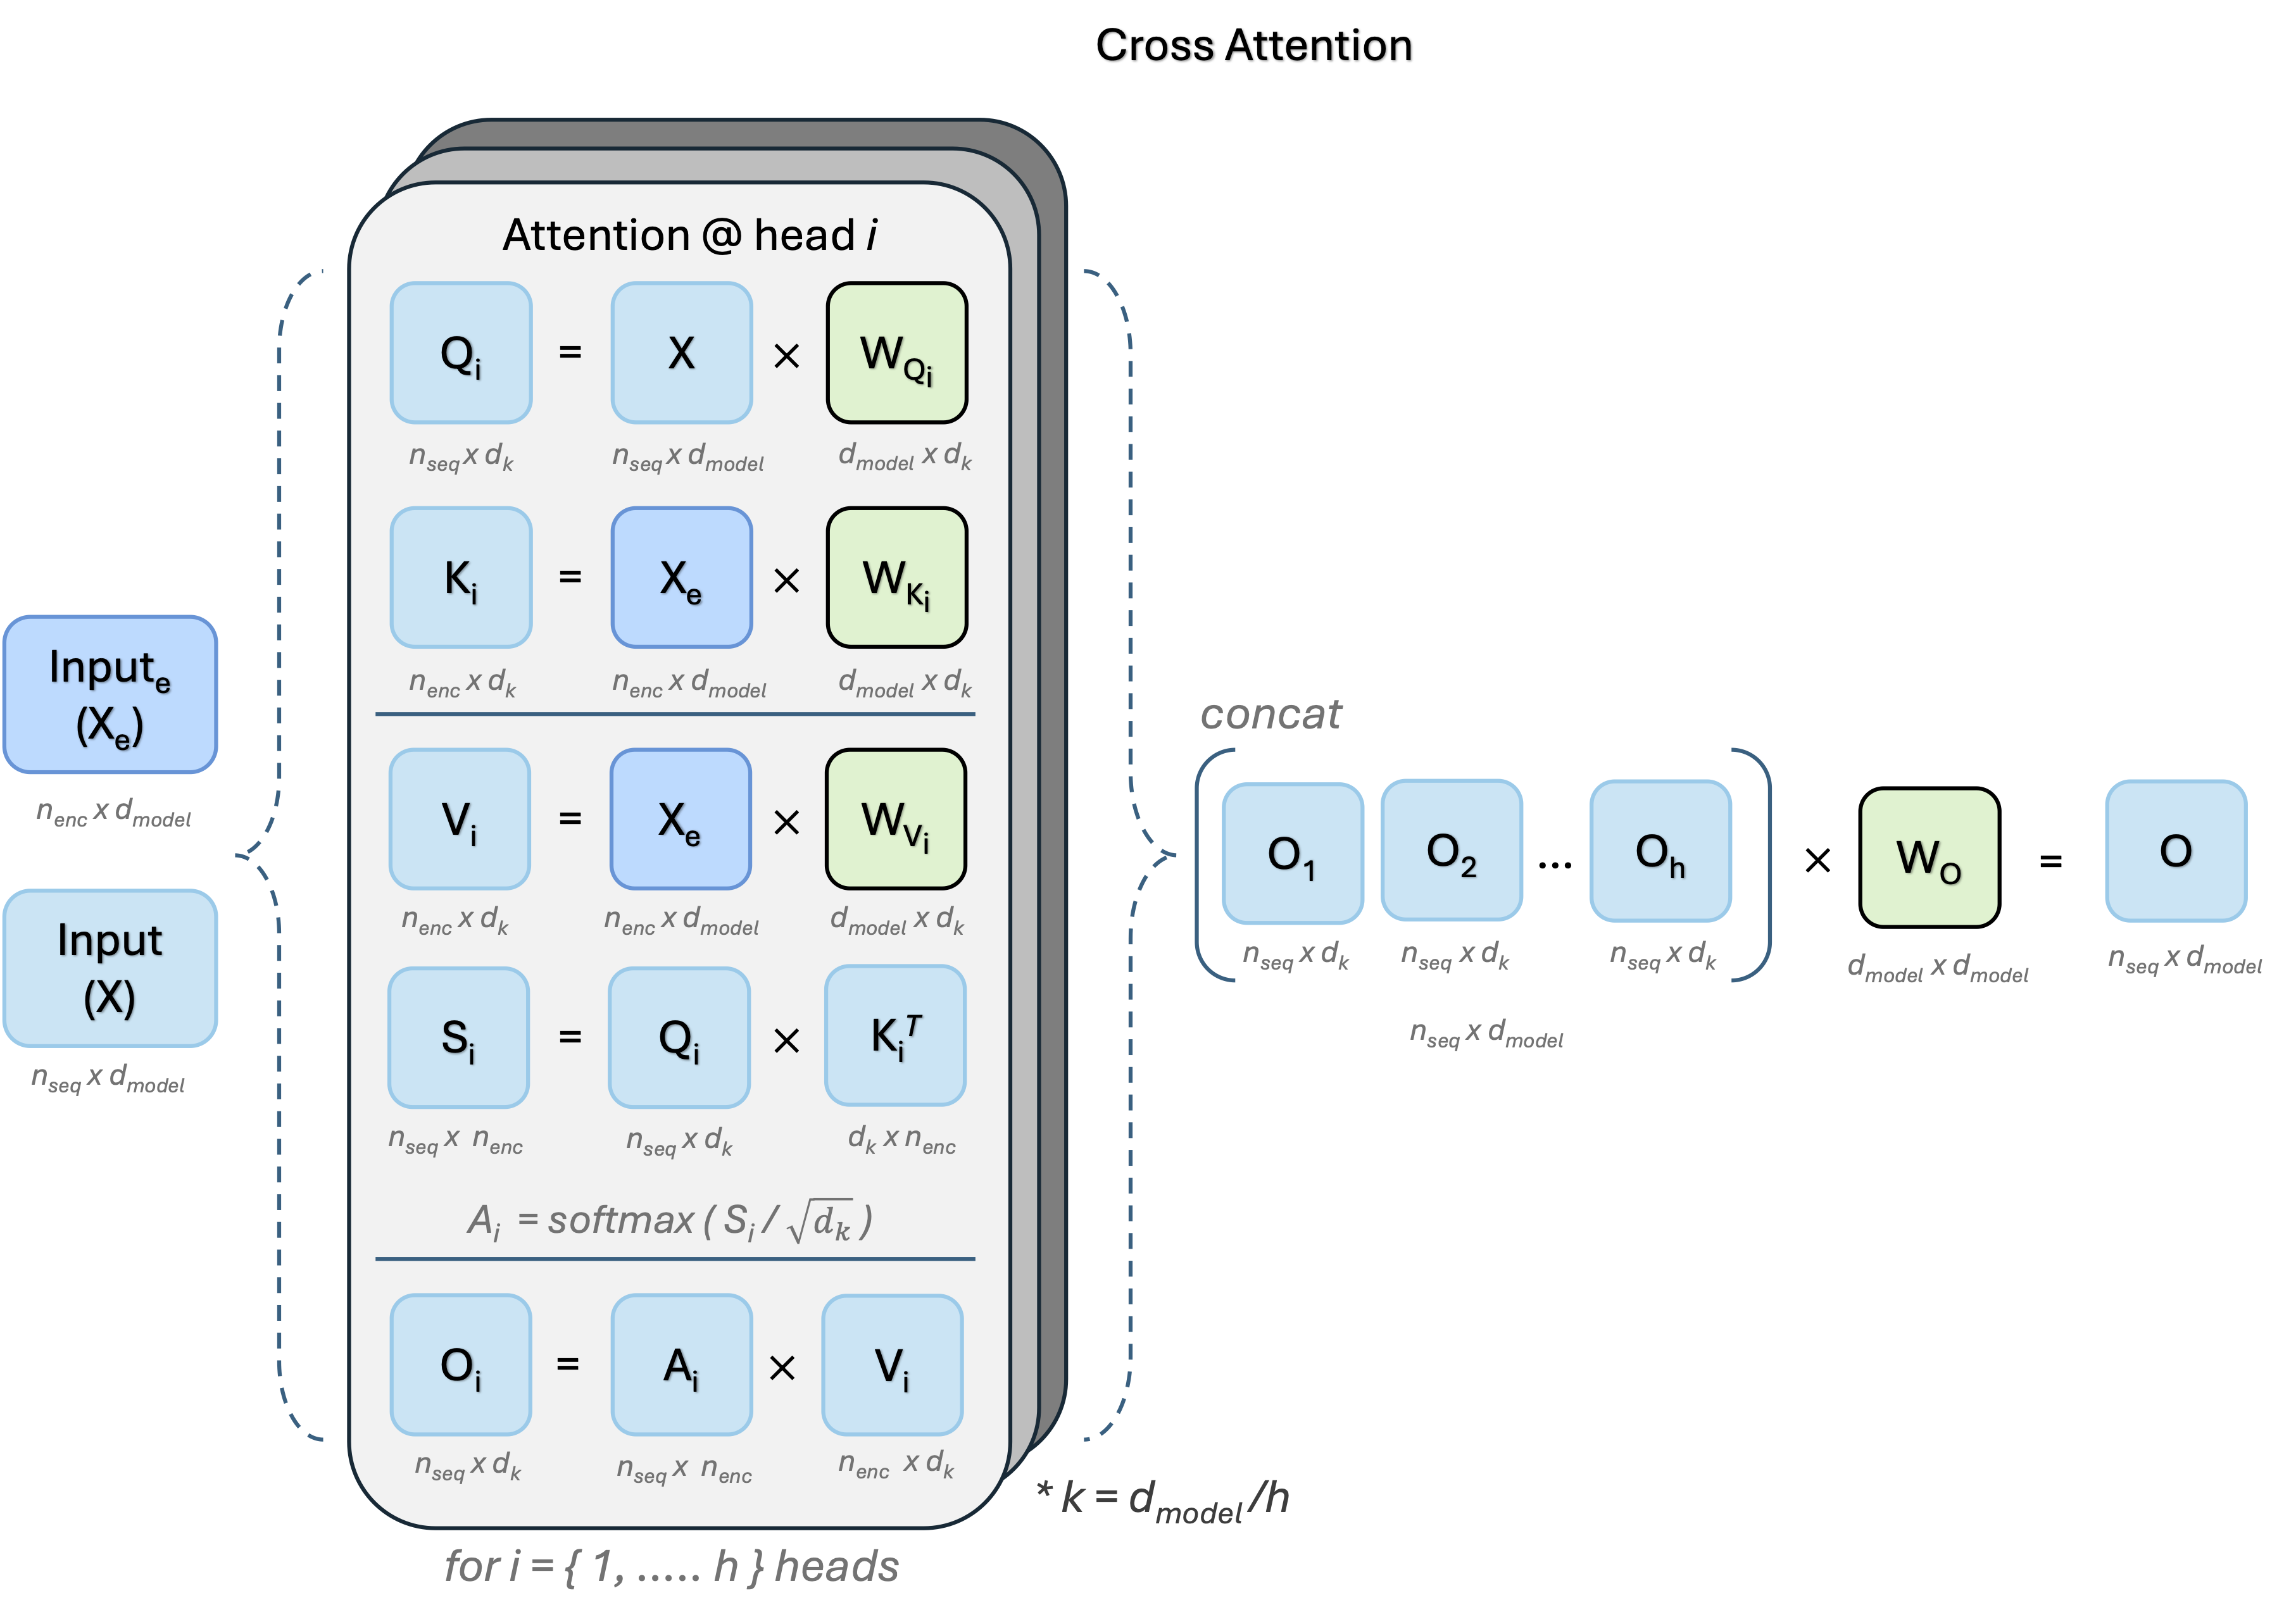
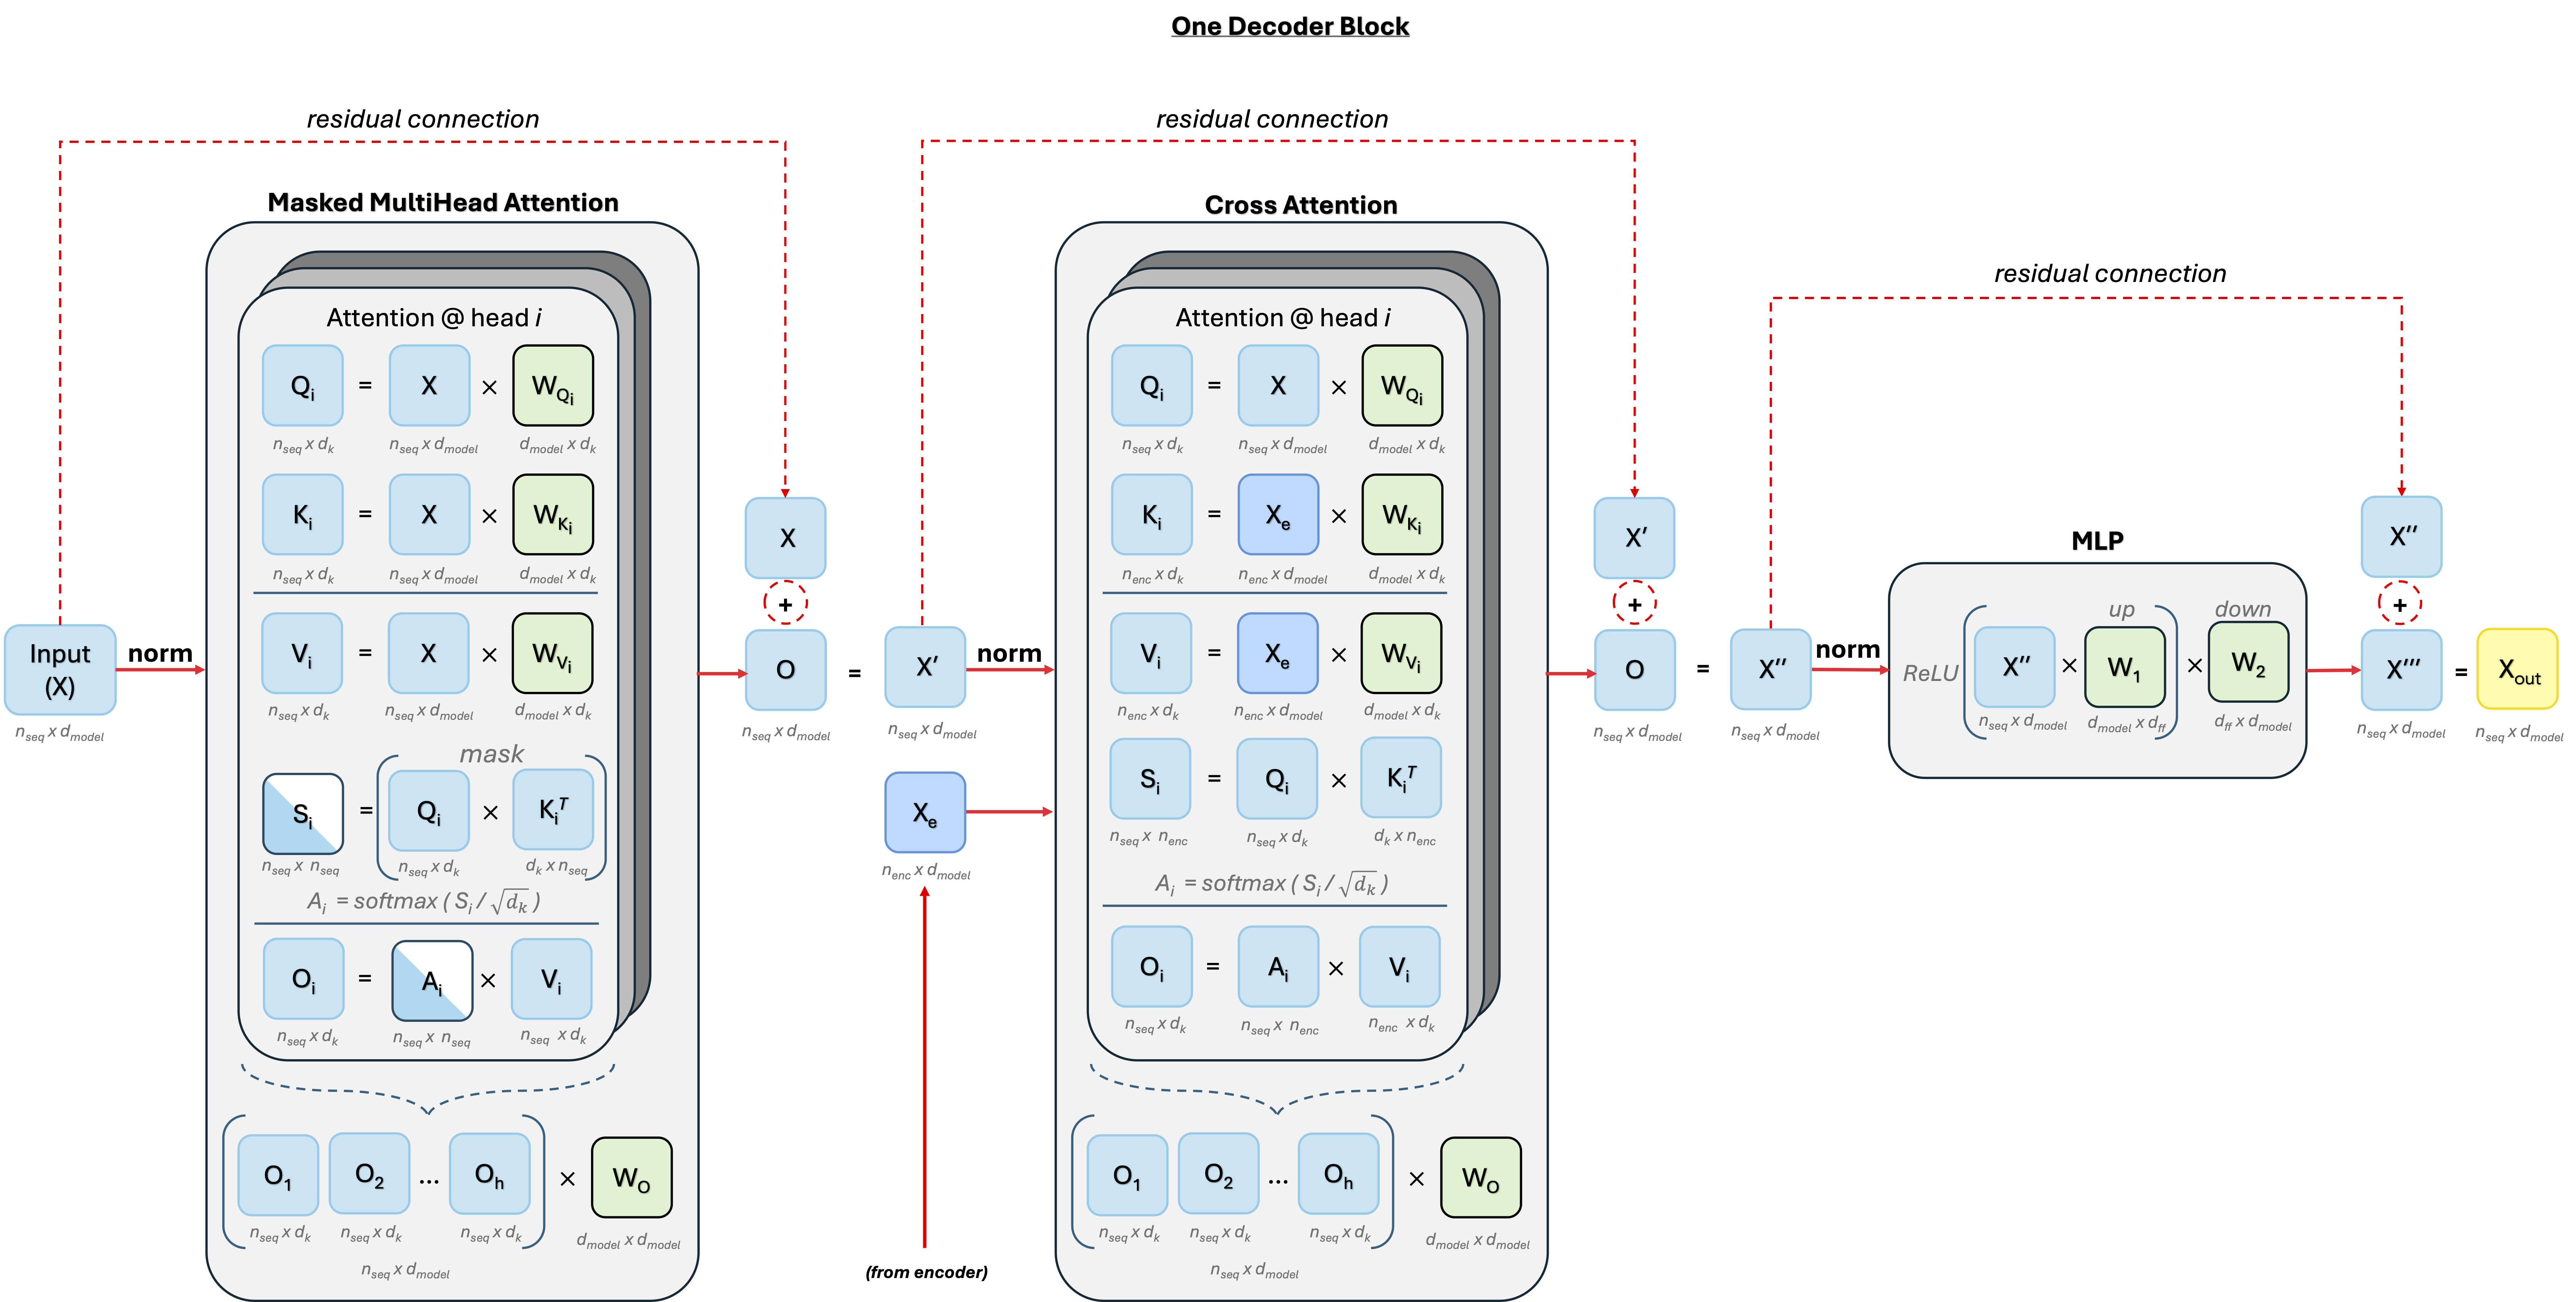
So we’ve built it! And it comes together easily enough after we spent so much time building up the components. But let’s take a step back here to talk about the role of the encoder - what, exactly, is its function. In Section 2, we spent a lot of time explaining why each step is important for things like ensuring training stability, preserving information, making sure our model can learn, and yes, for attention, how it relates words.
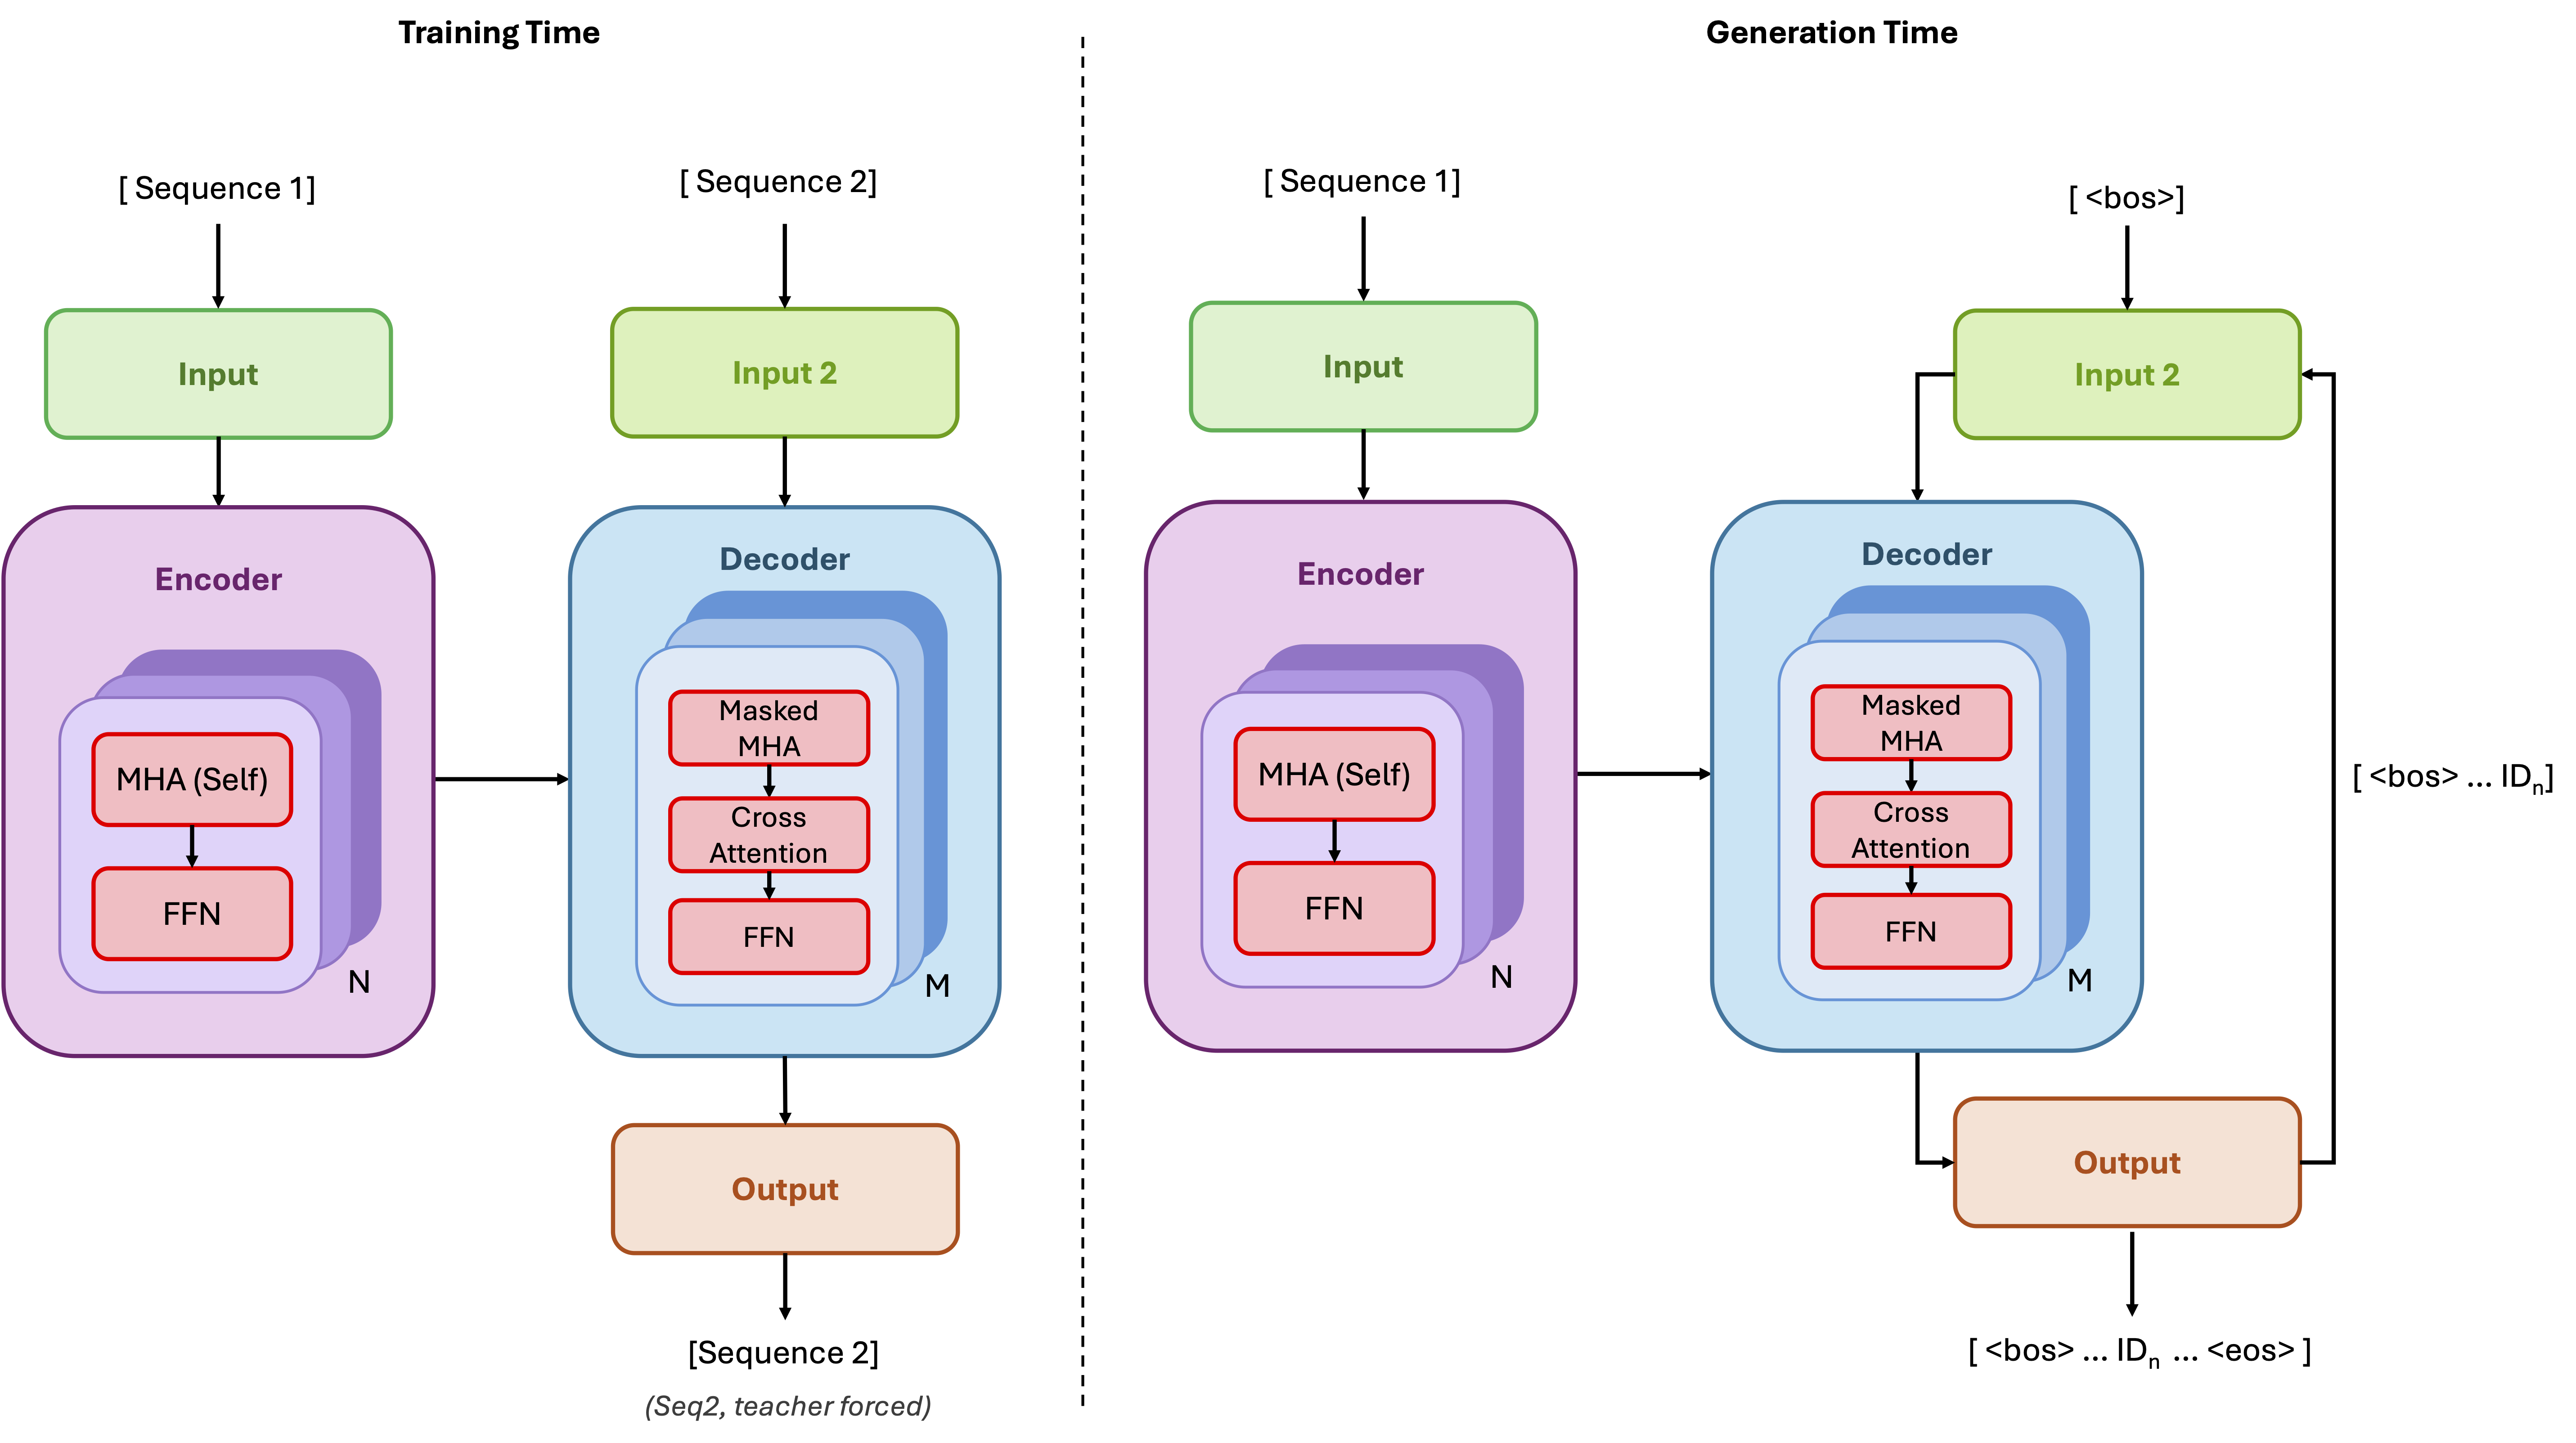
But it’s worth pausing here to look at what the encoder does in isolation, to understand why a full word generation model has both encoder and decoder components, and how exactly our words are getting transformed and related as they go through this step.
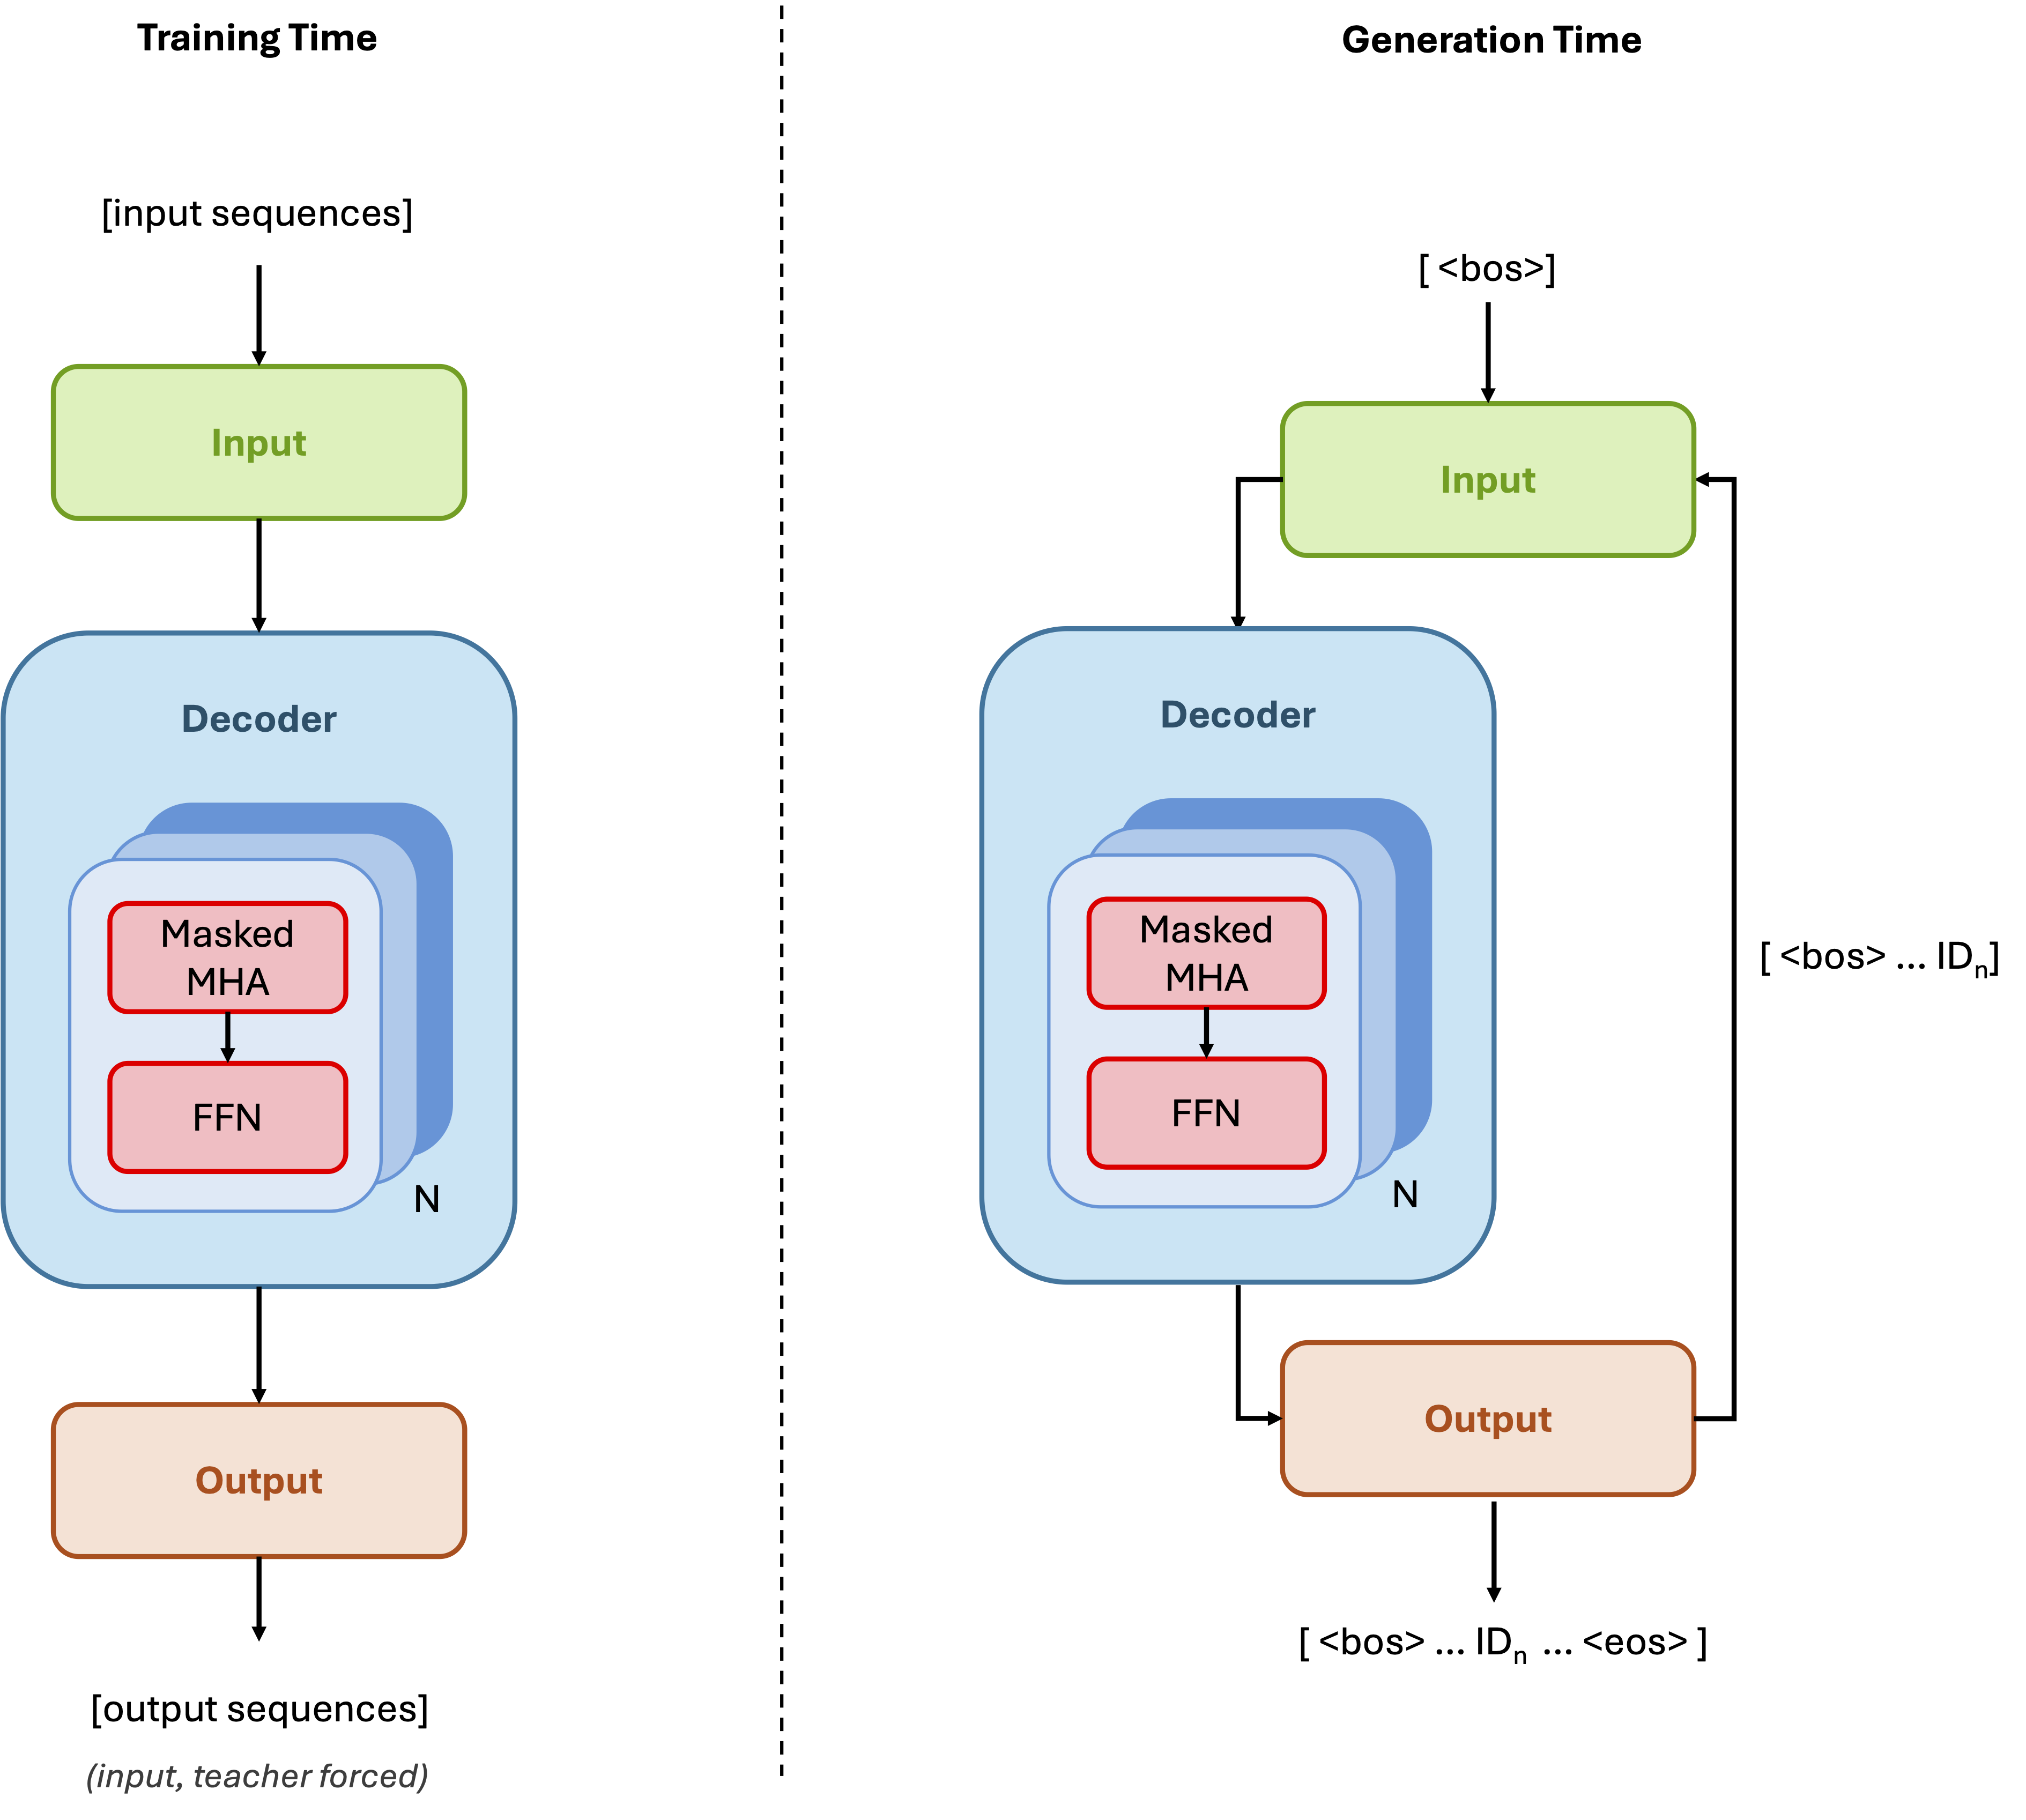
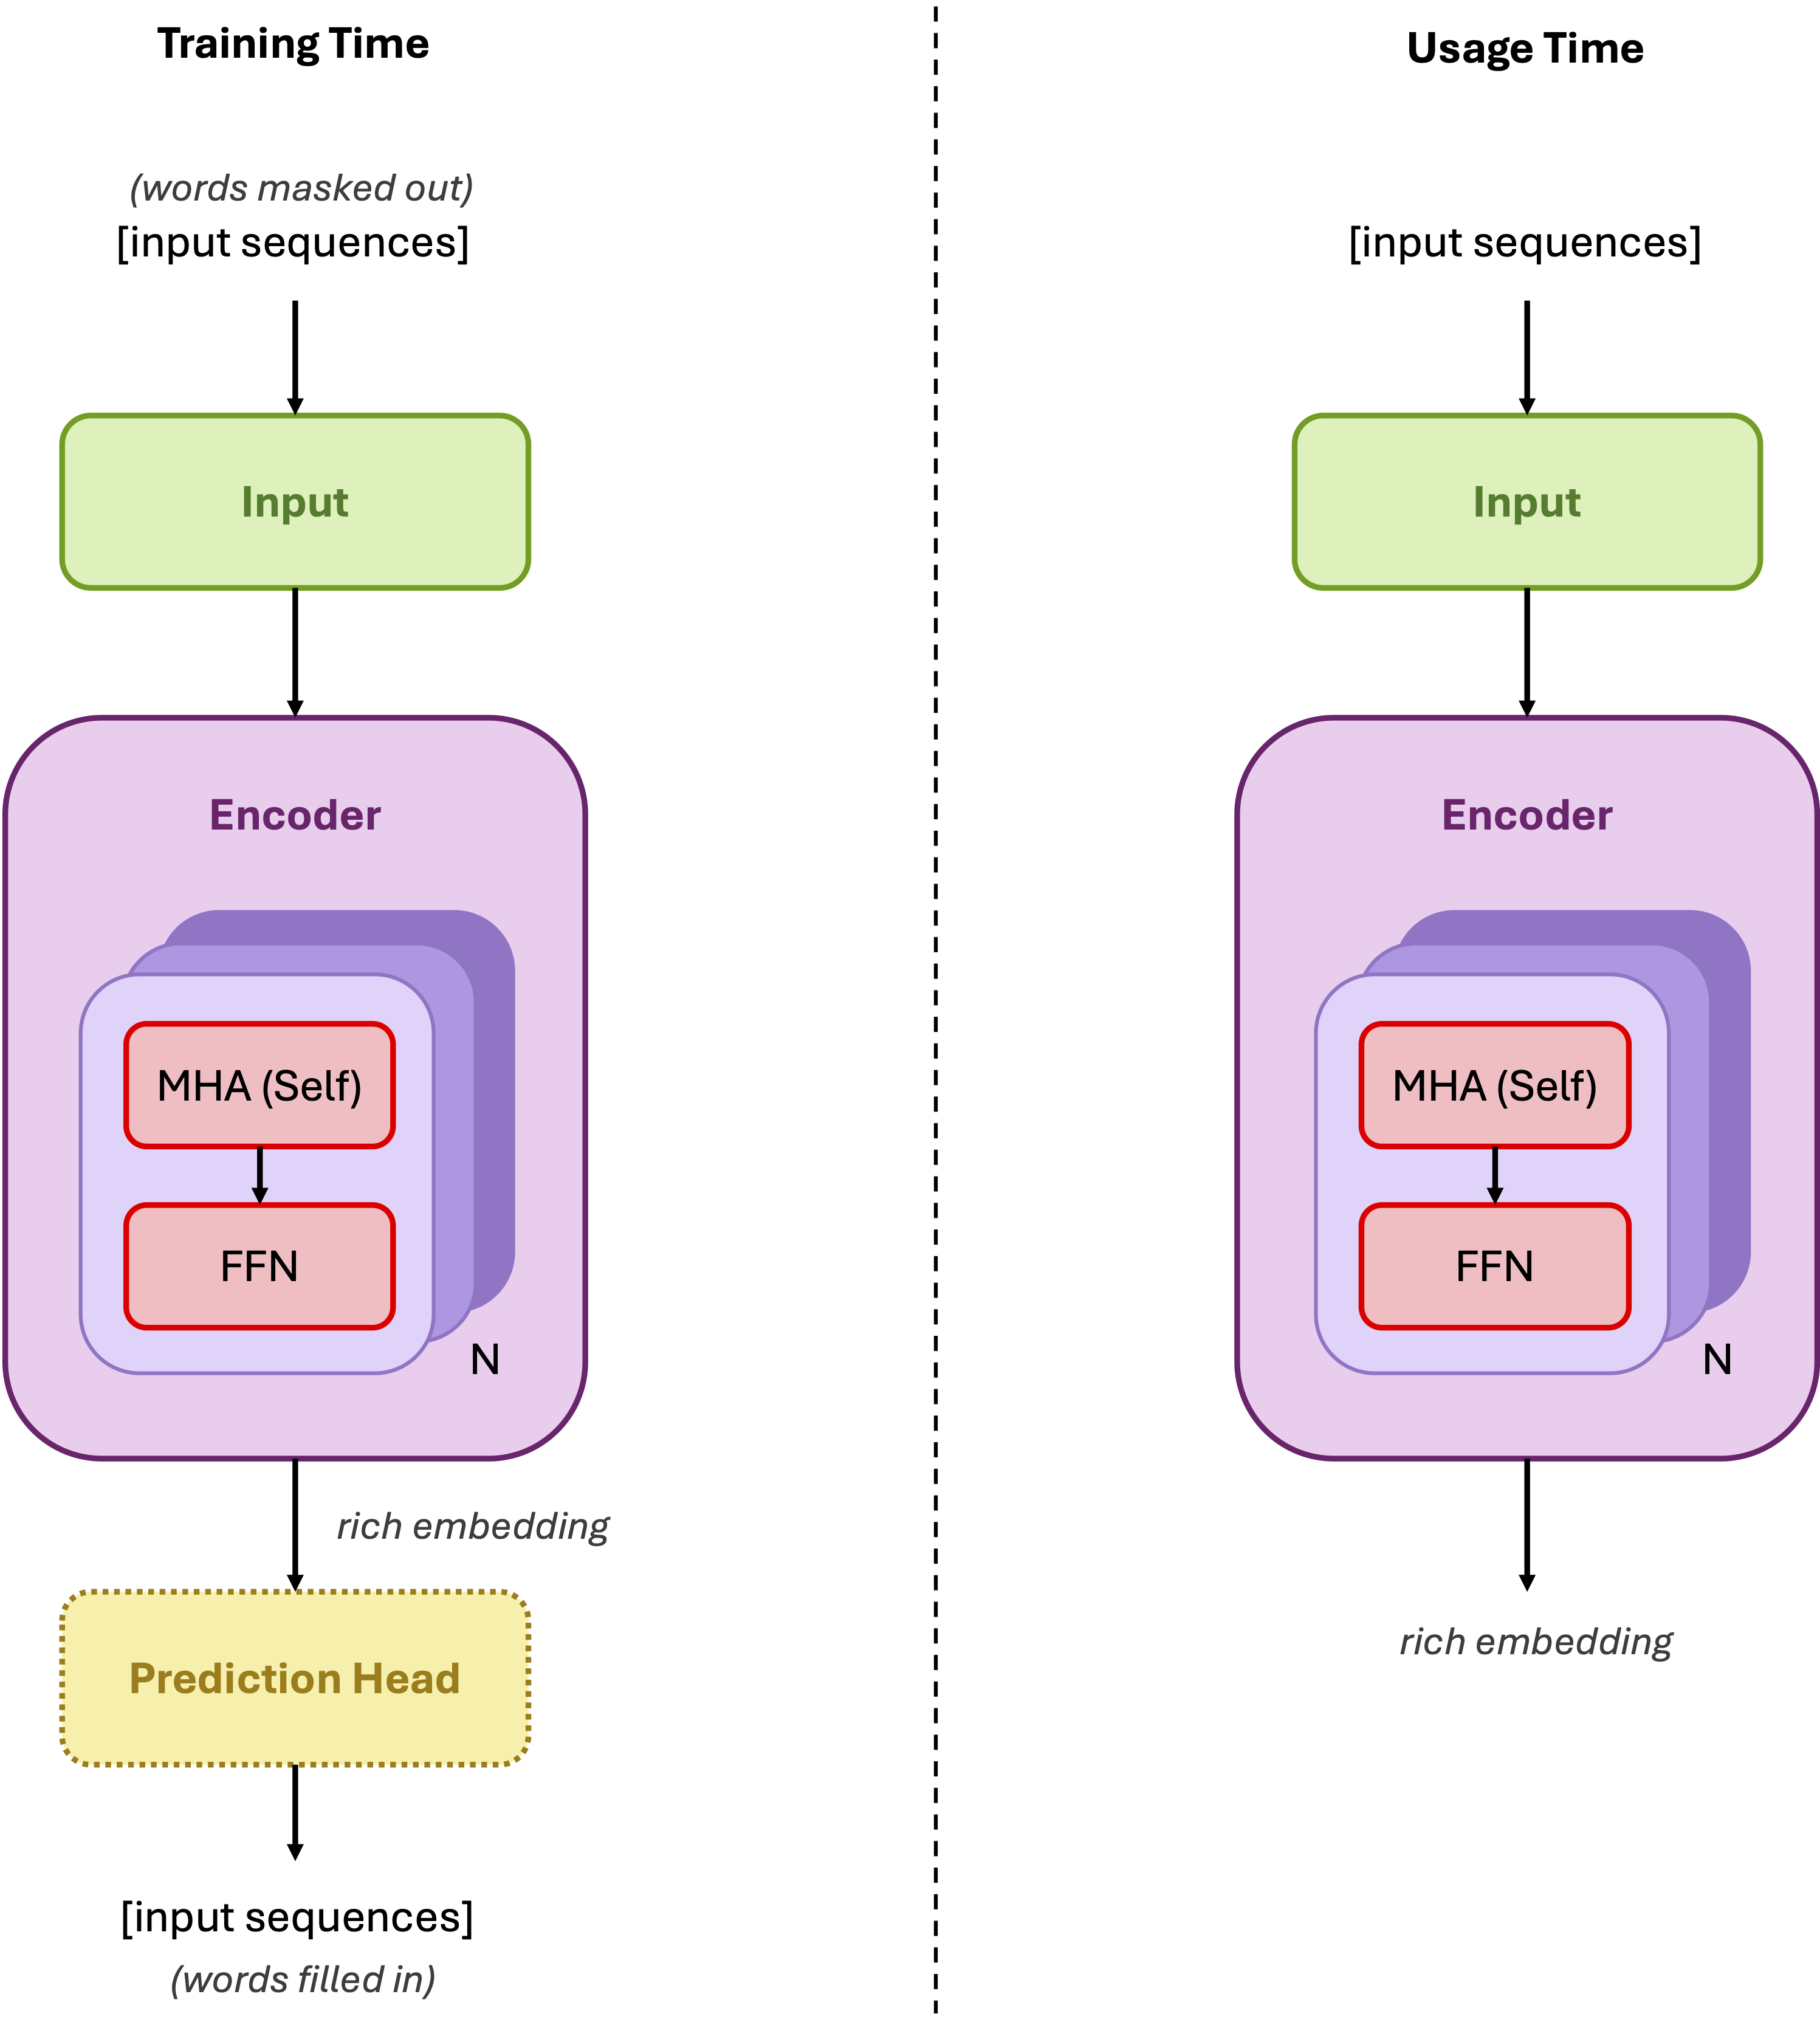
The thing is, which we’ll talk about a little later, the encoder isn’t necessarily where generation happens. Actually, as we’ll talk about in a bit, plenty of modern models have no encoder at all.
So then, what’s the point of the encoder? If later parts of the model, which we’ll discuss next, are where that literal next word is predicted, then why have an encoder at all? The answer is that the encoder is fundamentally understanding how the words in a sequence relate to one another to set up a decoder for success (and sometimes…. just for the sake of understanding in and of itself!). The key thing to understand is that, after the encoder stack, what comes out is rich, highly contextualized relationships between all of the words in the input sequence.
So to see exactly how this comes out, and why it can be so useful and important, let’s look a little more deeply at what we actually get out of the encoder.
3.2.1 Attention’s Output
Consider the following sentence moving through the encoder:
\[
\text{She poured water from the pitcher into the glass until it was}
\]
And let’s say it tokenizes conveniently at one token per word to:
\[
\text{a} \space\space \text{b} \space\space \text{c} \space\space \text{d} \space\space \text{e} \space\space \text{f} \space\space \text{g} \space\space \text{h} \space\space \text{i} \space\space \text{j} \space\space \text{k} \space\space \text{l}
\]
(note, it would be true that \(\text{e} = \text{h}\) - let’s keep them separate for clarity).
At the start, this sequence passes through the input funnel, and we end up with an embedding of size, say 13 \(\times\) 5. Imagine that this model’s maximum sequence length is 13 - our sentence has 12 words so far - and our embedding size and therefore \(d_{\text{model}}\) is 5.
\[
X_{in} ( \in \space \mathbb{R}^{13 \times 5}) = \space \begin{matrix}
a_1 & a_2 & a_3 & a_4 & a_5\\
... \\
k_1 & k_2 & k_3 & k_4 & k_5\\
... \\
m_1 & m_2 & m_3 & m_4 & m_5\\
\end{matrix}
\space \begin{matrix}
\space ← \textit{embedding for "She"} \\
\space \\
\space ← \textit{embedding for "it"} \\
\space \\
\space ← \textit{padding token at end} \\
\end{matrix}
\]
At the start, “it” is completely context-free: the vector \([k_1 \space k_2 \space k_3 \space k_4 \space k_5]\) is the same “it” that would be in any sentence ever written when input through the input portion of the model. As far as just this vector is concerned, “it” could be standing in for the water, the pitcher, the glass… there’s no way to know because right now, it exists completely independently from those words.
The next major transformation that comes is attention. During attention, this understanding of “it” becomes a combination of every other word in the sentence.
The Projections
Attention’s first move is to produce the \(Q\), \(K\), and \(V\) matrices - query, key, and value - which are constructed by multiplying the input by three learned weight matrices:
\[
Q = X_{in} W_Q, \qquad K = X_{in} W_K, \qquad V = X_{in} W_V
\]
Each of the resulting \(Q\), \(K\), and \(V\) matrices is a 13 x 5, the same shape as the input, and also, importantly, contains one vector within that pertains to “it”. I will leave it to the reader to work through the complete math if you want (re-reference the “attention” section for exactly how these matrices are calculated), but here, let’s just look at exactly what is computed for “it.” “It”’s query vector \(Q_k\) is the row \([k_1\ k_2\ k_3\ k_4\ k_5]\) times the whole matrix \(W_Q\):
\[
Q_k =
\begin{bmatrix} k_1 & k_2 & k_3 & k_4 & k_5 \end{bmatrix}
\begin{bmatrix}
w_{Q11} & w_{Q12} & w_{Q13} & w_{Q14} & w_{Q15} \\
w_{Q21} & w_{Q22} & w_{Q23} & w_{Q24} & w_{Q25} \\
w_{Q31} & w_{Q32} & w_{Q33} & w_{Q34} & w_{Q35} \\
w_{Q41} & w_{Q42} & w_{Q43} & w_{Q44} & w_{Q45} \\
w_{Q51} & w_{Q52} & w_{Q53} & w_{Q54} & w_{Q55} \\
\end{bmatrix}
\]
Written out fully, entry by entry, that query vector is:
\[
Q_k =
\begin{bmatrix}
k_1 w_{Q11} + k_2 w_{Q21} + k_3 w_{Q31} + k_4 w_{Q41} + k_5 w_{Q51} \\[4pt]
k_1 w_{Q12} + k_2 w_{Q22} + k_3 w_{Q32} + k_4 w_{Q42} + k_5 w_{Q52} \\[4pt]
k_1 w_{Q13} + k_2 w_{Q23} + k_3 w_{Q33} + k_4 w_{Q43} + k_5 w_{Q53} \\[4pt]
k_1 w_{Q14} + k_2 w_{Q24} + k_3 w_{Q34} + k_4 w_{Q44} + k_5 w_{Q54} \\[4pt]
k_1 w_{Q15} + k_2 w_{Q25} + k_3 w_{Q35} + k_4 w_{Q45} + k_5 w_{Q55} \\
\end{bmatrix}^{\top}
\]
Note the transpose: I wrote this as a column vector so it would fit, but note that this is a row of the resulting Q in the end.
And \(K_k\) and \(V_k\) are the exact same operation with \(W_K\) and \(W_V\):
\[
K_k = \begin{bmatrix} k_1 & \cdots & k_5 \end{bmatrix} W_K, \qquad
V_k = \begin{bmatrix} k_1 & \cdots & k_5 \end{bmatrix} W_V
\]
So you’ll notice, “it” is still context-free at this point. Every single term in every one of those sums is some \(k_i\) times a weight. Every row in \(Q\), \(K\), and \(V\) serves to contextualize a word against its own embedding - not yet at all against the other words. They are three different linear reshufflings of the same standalone token, knowing nothing yet about the rest of the sentence.
The Attention Calculation
Now. This might prompt a very fair question: if all three are just re-projecting “it” into itself, why do we need three of them? Wouldn’t one be enough? And the answer is in that interpretation that \(Q\) (query), \(K\) (key), and \(V\) (value) are “looking for different things”. But it’s worth being really clear about what that means as we see the next steps in the calculation of attention.
The main idea is that we need the model to be free to make these roles differ. We know a query (\(Q\)), asks “what do I refer to?”, a key (\(K\)), says “here’s what I offer to anyone looking”, and a value (\(V\)) says “here’s what I’ll actually contribute if attended to.” But the important thing is that those can be naturally reflected in how these matrices are used.
Attention starts by multiplying \(Q\) and \(K^\top\). Immediately, look at what that does. To compute how much “it” should attend to “glass,” we take “it”’s query row and dot it with “glass”’s key row. Writing \(Q_k\) for “it”’s query (remember - “it” was token “k”) and \(K_i\) for “glass”’s key (glass is token \(i\)), that single score is:
\[
S_{k,i} \;=\; Q_k \cdot K_i \;=\; Q_{k,1}K_{i,1} + Q_{k,2}K_{i,2} + Q_{k,3}K_{i,3} + Q_{k,4}K_{i,4} + Q_{k,5}K_{i,5}
\]
This is one number - a single score measuring how well “it” - as a seeker - lines up with “glass” - as a target. The dot product here does this specifically - it is exactly a measure of alignment between two vectors. It’s large when \(Q_k\) and \(K_i\) point the same way, small (or negative) when they don’t. So this operation is literally asking “does what ‘it’ is looking for match what ‘glass’ is offering?” - and it answers with a number.
So \(Q\) and \(K\) can’t be the same matrix. The dot product \(Q_k \cdot K_i\) needs to be able to compare two different words in two different roles. Here, “it” as the one doing the looking, “glass” as the one being looked at. You’ll note that a different part of this calculation does the opposite - \(S_{i,k}\) gets to ask how much “it” matches what “glass” is looking for. If \(W_Q\) and \(W_K\) were identical, then a word’s “looking” vector would always equal its “being looked at” vector. The score of “it” attending to “glass” (\(Q_k \cdot K_i\)) would be forced to equal the score of “glass” attending to “it” (\(Q_i \cdot K_k\)), because both would just be the same dot product of the same two projected vectors. So attention would be symmetric, and every relationship mutual. This is of course not how real language works. “It” really needs to see “glass” to understand what it means, while “glass” doesn’t really get any extra contextualization from “it”. Separating \(W_Q\) and \(W_K\) is precisely what lets the query-side and key-side of a word diverge, and that’s what makes asymmetric attention possible at all.
When we look at how this plays out fully for “it”, we get a complete row of scores out of this operation. “It” gets to play seeker against every single other word in the sequence:
\[
S_k \;=\; \big[\; Q_k \cdot K_a \;\;\; Q_k \cdot K_b \;\;\; \cdots \;\;\; Q_k \cdot K_i \;\;\; \cdots \;\;\; Q_k \cdot K_l \;\big]
\]
These scores get scaled and softmaxed into final attention weights, which say, for each word, how much “it” aligns with it.
Attention’s Output
So \(Q\) and \(K\) are “used up” in computing attention scores. We now just have the artifact of scores that says how much a word needs to pay attention to all the others. That’s why we need that third matrix - \(V\) - the value - to come in and let us actually weight the content. Recall that the next step in the attention calculation will be to calculate \(O\):
\[
O_k \;=\; A_{k,a}V_a + A_{k,b}V_b + \cdots + A_{k,i}V_i + \cdots + A_{k,l}V_l
\]
Each \(V\) there is itself a 5-dimensional row. So written out fully, dimension by dimension, the first component of “it”’s new vector is:
\[
O_{k,1} = A_{k,a}\,V_{a,1} + A_{k,b}\,V_{b,1} + A_{k,c}\,V_{c,1} + \cdots + A_{k,i}\,V_{i,1} + \cdots + A_{k,l}\,V_{l,1}
\]
So now, finally, the portion of \(O\) that is relevant to \(k\) is a combination of \(a\)’s, \(b\)’s, \(c\)’s, \(i\)’s - it’s fully contextualized by other words’ value vectors, weighted by how much attention it needs to give them. All of “she”, “poured”, “glass” are now literally, arithmetically part of what “it” is. So exactly where our understanding of “it” stops being context-free is in this calculation.
So where \(Q\) and \(K\) exist to decide relevance, \(V\) is what gets delivered once relevance is decided. The “key” says what about a word is relevant for matching (stuff like, this is a concrete, referable noun). That can, and should, be completely different from the information it contributes once matched - its full rich meaning.
So the three roles in constructing this final \(O\) aren’t three arbitrary labels - they really do reflect where and how the math of attention relates them. \(Q\) and \(K\) are used in a dot product, which compares them. \(V\) gets used in a weighted sum, so it’s the content. All three matrices, though they begin without any cross-context, are used in a way that ends up with a rich, weighted understanding between each word, and every other word.
The Values
Let’s look concretely at how some made up values for these steps might actually affect how a word gets understood. Let’s say we have the following attention weights for “it” (remember, this is our result for softmax, scaled, \(Q \times K^\top\) - it says “how much do I care about every other word”):
\[
A_k = \big[\, \underbrace{0.04}_{\text{She}}\ \ \underbrace{0.08}_{\text{poured}}\ \ \underbrace{0.14}_{\text{water}}\ \ \underbrace{0.03}_{\text{from}}\ \ \underbrace{0.03}_{\text{the}}\ \ \underbrace{0.05}_{\text{pitcher}}\ \ \underbrace{0.04}_{\text{into}}\ \ \underbrace{0.03}_{\text{the}}\ \ \underbrace{\mathbf{0.42}}_{\textbf{glass}}\ \ \underbrace{0.03}_{\text{until}}\ \ \underbrace{0.06}_{\text{it}}\ \ \underbrace{0.05}_{\text{was}} \,\big]
\]
In this example, most of “it”’s attention (0.42) is pointing to “glass”.
The weights \(A_{k,j}\) decide how much of each word becomes a part of this word’s understanding. With “it”’s weight concentrated on “glass” (\(A_{k,i} = 0.42\)) (with smaller amounts on “water” and “poured”), the term \(V_i\) (glass) dominates the sum. What this means, is that \(O_k\) comes out close to glass’s value vector, with a little bit of “water” and a tiny bit of “poured”, and not much else. In vector terms, that means “it” has been rebuilt to point mostly to where “glass” points. Its new representation is, in effect, a stand-in for glass. And that is exactly how “it” is functioning in this sentence.
If you change the weights, you change what “it” becomes. Had the attention instead put 0.42 on “pitcher”, the identical formula would rebuild “it” toward the pitcher’s vector, and “it” would come to mean the pitcher. The attention weights \(A\) decide the “recipe” for rebuilding a word from its context. And learning what weights are right to get this right is a large part of what the model spends training figuring out.
So, coming out of the attention calculation, we have words as re-contextualized vectors, carrying with them combinations of all other words in the sequence, and better aligning themselves in vector space with other words that are close to their meaning. But of course, the encoder isn’t done!
But one quick addition before we move on. We walked through that whole attention calculation as if there were a single set of \(Q\), \(K\), \(V\). Of course, we’ve established that attention is typically multi-head, so several of these run in parallel, and we’d have many \(O\)’s at the end instead. The idea is that “it” gets to ask many questions at once about what it refers to. One head might put its weight on “glass” to catch the object being referred to, while another tracks “water” as what’s being poured into it. Each head produces its own rebuilt version of “it,” and \(W_O\) then combines them, letting the model weigh which of those many questions mattered most for this particular “it,” in this particular sentence.
I won’t go through that math again here (the multi-head section covers it). And importantly, it doesn’t change the interpretation of what comes out: “it” is still a representation rebuilt from its context, just assembled from several complementary views of that context instead of one. When \(W_O\) mixes the heads together, it is an additional learned transformation, so the model does get an opportunity to learn how to flexibly combine information here as well. But importantly, as we’re about to see, it’s still a linear combination, which is why the next portion is needed.
3.2.2 The MLP’s Output
Coming out of attention, “it” is now a rich, contextualized vector, which carries information about “glass”, “water”, “pitcher”, all weighted by relevance. So it’s fair to ask: couldn’t we stop there? What’s left to do to a vector that already knows what it means?
The issue is that the \(O\) that comes out of attention:
\[
O_k = A_{k,a}V_a + A_{k,b}V_b + \cdots + A_{k,i}V_i + \cdots + A_{k,l}V_l
\]
Is some combination of the existing value vectors, scaled by a weight, and the weights are positive and sum to 1. So \(O_k\) is really interpreted as a weighted average of value vectors the sentence already contained. A weighted average, by definition, is only ever a mix of the things you’re averaging - it can’t produce anything genuinely new. So while attention is an excellent information retriever - deciding which information to gather and pull together - it never actually does anything to that information once gathered. It can only hand off a combination of what was already there.
(Even with multi-head, this stays true in spirit: \(W_O\) mixes the heads with a learned linear map, which is more than an average, but still linear.)
The feed-forward network (FFN) or multi-layer perceptron (MLP) - these are the same exact thing with interchangeable names - is instead where the learning from the information really happens. And it’s because it’s a non-linear transformation.
Recall the shape of the MLP from Section 2:
\[
\text{FFN}(x) = \text{ReLU}(x \cdot W_1)\,W_2
\]
That ReLU is the first time the network applies an elementwise non-linear transformation to a token’s own features. Attention did contain a non-linearity in the softmax, which decides how much of each value vector to blend together, but the result from that, \(O_k\), is a weighted average of value vectors that were already there. Without the MLP, every token is just a blend of existing value vectors. The network creates genuinely new features in the MLP.
📌 Note: Why non-linearity is non-negotiable. You may recall that non-linearity is the single property that lets a neural network learn anything that a plain matrix multiply couldn’t. If you’re already comfortable with why neural nets need activation functions, then read ahead. But if you need a refresher, we go into all of the details on why neural nets in general must contain non-linearities in Appendix 3 below.
There is a second thing the FFN does, that is also very important, which is that it actually runs on tokens independently. Each vector for each token is transformed alone, with no re-referencing the other tokens. This is exactly what we want - a division of labor. Attention already contextualized this token using the words around it. The MLP’s job isn’t to repeat that process - it’s to transform tokens into a space where we can do useful things with them.